<?xml version="1.0" encoding="utf-8"?><feed xmlns="http://www.w3.org/2005/Atom" ><generator uri="https://jekyllrb.com/" version="4.4.1">Jekyll</generator><link href="https://matthiasmunz.de/en/feed.xml" rel="self" type="application/atom+xml" /><link href="https://matthiasmunz.de/en/" rel="alternate" type="text/html" /><updated>2026-10-06T16:45:22+02:00</updated><id>https://matthiasmunz.de/feed.xml</id><title type="html">MatthiasMunz.de 👋</title><subtitle>{&quot;en&quot;=&gt;&quot;Explore, Learn, Decide Better.&quot;, &quot;de&quot;=&gt;&quot;Explore, Learn, Decide Better.&quot;}</subtitle><author><name>Matthias Munz</name></author><entry xml:lang="en"><title type="html">My 3D-printed aerobridge for my gravel bike</title><link href="https://matthiasmunz.de/en/3d_printing_aerobridge/" rel="alternate" type="text/html" title="My 3D-printed aerobridge for my gravel bike" /><published>2026-09-06T00:00:00+02:00</published><updated>2026-09-10T17:05:55+02:00</updated><id>https://matthiasmunz.de/3d_printing_aerobridge</id><content type="html" xml:base="https://matthiasmunz.de/3d_printing_aerobridge/"><![CDATA[<p>This article is about one of my first original 3D designs, which I printed myself and which is still in use today in a modified form. You can find more information about my 3D printer and the software I used for modeling <a href="">here</a>.</p>

<p>For my <a href="">bike trip across Germany</a>, I wanted to try out an additional grip position on the long daily stages. That’s why I equipped my <strong>Cube Nuroad Pro FE</strong> with a triathlon handlebar attachment. Now I still needed an aerobridge to securely mount my cell phone and its holder between or in front of the two handlebar extensions.</p>

<p>Since the tour was just around the corner, ordering online was no longer an option. So I spontaneously set out to design and print a suitable aerobridge myself. After all, I already had the 3D printer.</p>

<p>There are now three versions of it. And as is so often the case with 3D printing, it wasn’t until I put it to practical use that I realized what still needed to be improved in the original design.</p>

<script type="module" src="https://ajax.googleapis.com/ajax/libs/model-viewer/3.4.0/model-viewer.min.js"></script>

<style>
  model-viewer {
    width: 100%;
    height: 500px;
    display: block;
  }
</style>

<h2 id="aerobridge-v1">Aerobridge v1</h2>

<p>The first version consisted of a crossbar between the two trailers, secured with two cable ties. An inverted U extended forward from this crossbar. I was able to attach my phone mount to the front leg of the inverted U.</p>

<model-viewer src="/assets/glb/Aerobridge.glb" alt="Aerobridge v1 for the handlebar mount on my gravel bike" auto-rotate="" camera-controls=""></model-viewer>

<p>The concept worked, but the crossbar was a bit too flimsy for my liking. That’s why I developed a second version before my cross-country trip through Germany.</p>

<h2 id="aerobridge-v2">Aerobridge v2</h2>

<p>Bei <strong>v2</strong> habe ich vor allem die Querstrebe massiver ausgelegt. Die grundsätzliche Konstruktion mit dem nach vorne ragenden U blieb erhalten.</p>

<model-viewer src="/assets/glb/Aerobridge_v2.glb" alt="Aerobridge v2 mit verstärkter Querstrebe" auto-rotate="" camera-controls=""></model-viewer>

<p>Auf meiner Deutschlanddurchquerung zeigte sich dann allerdings eine andere Schwachstelle. Durch das Gewicht von Handy und Halterung konnte das nach vorne ragende U während der Fahrt leicht wippen. Irgendwann brach es am Übergang zur Querstrebe an.</p>

<p>Damit war klar: Die Konstruktion musste einfacher werden.</p>

<h2 id="aerobridge-v3">Aerobridge v3</h2>

<p>For <strong>v3</strong>, I therefore omitted the entire U-shape. Essentially, all that remains is the crossbar, to which the phone mount can be attached directly.</p>

<p>&lt;model-viewer src=”/assets/glb/Aerobridge_v3.glb”
              alt=“Aerobridge v3 as a simplified crossbar”
              auto-rotate
              camera-controls&gt;&lt;/model-viewer&gt;</p>

<p>I printed the Aerobridge using <strong>PLA with 30% grid infill</strong>. Mechanically, this significantly simpler design has performed well so far.</p>

<p>However, on my last multi-day trip to Basel, the next weak point became apparent: <strong>the material’s temperature resistance</strong>.</p>

<p>In the area of the cell phone mount, the Aerobridge gave way under the clamping force and became visibly constricted at that point. This made me want to tighten the mount even more, which further exacerbated the deformation.</p>

<p>Although PLA is very easy to print, it isn’t necessarily ideal for components subjected to constant stress in the sun. Depending on the material, it begins to soften significantly as early as approximately <strong>50 to 60 °C</strong> and deforms under stress (<a href="https://help.prusa3d.com/de/filament-material-guide">Prusa Filament Material Guide</a>).</p>

<h2 id="next-attempt-petg">Next Attempt: PETG</h2>

<p>I will therefore print the next Aerobridge out of <strong>PETG</strong>.</p>

<p>PETG is tougher and less brittle than PLA, making it often a better choice for components subject to mechanical stress. Above all, it is more heat-resistant: Depending on the filament, its heat deflection temperature is approximately <strong>70 to 90 °C</strong>, whereas PLA can become problematic as early as <strong>50 to 60 °C</strong> (<a href="https://help.prusa3d.com/de/article/petg_2059">Prusa</a>).</p>

<p>Whether PETG permanently solves the heat problem will become clear the next time I use it.</p>

<p>For me, the Aerobridge is a great example of what actually interests me about 3D printing: <strong>designing a concrete idea, testing it, discovering weaknesses, and improving the model step by step.</strong></p>]]></content><author><name>Matthias Munz</name></author><category term="3D Printing" /><summary type="html"><![CDATA[This article is about one of my first original 3D designs, which I printed myself and which is still in use today in a modified form. You can find more information about my 3D printer and the software I used for modeling here.]]></summary></entry><entry xml:lang="en"><title type="html">My first 3D printer: Anycubic Vyper</title><link href="https://matthiasmunz.de/en/Anycubic_Vyper/" rel="alternate" type="text/html" title="My first 3D printer: Anycubic Vyper" /><published>2026-08-30T00:00:00+02:00</published><updated>2026-09-04T22:44:25+02:00</updated><id>https://matthiasmunz.de/Anycubic_Vyper</id><content type="html" xml:base="https://matthiasmunz.de/Anycubic_Vyper/"><![CDATA[<p>3D printing is no longer a technology reserved only for companies, research institutions, or ambitious hobbyists. The first comparatively affordable desktop 3D printers came onto the market in the late 2000s. One of the best-known early examples was the MakerBot CupCake CNC from 2009. At the time, it cost around 750 US dollars and was still supplied as a kit (<a href="https://www.wired.com/2009/08/makerbot/">Wired</a>).</p>

<p>A lot has changed since then. The machines are now not only cheaper, but above all faster, more reliable, and much easier to use. The most common devices are so-called <strong>FDM printers</strong>. FDM stands for <em>Fused Deposition Modeling</em>, commonly referred to in German as Schmelzschichtung. In this process, a plastic filament is heated and built up layer by layer through a nozzle to create a three-dimensional object (<a href="https://www.stratasys.com/en/guide-to-3d-printing/technologies-and-materials/fdm-technology/">Stratasys</a>).</p>

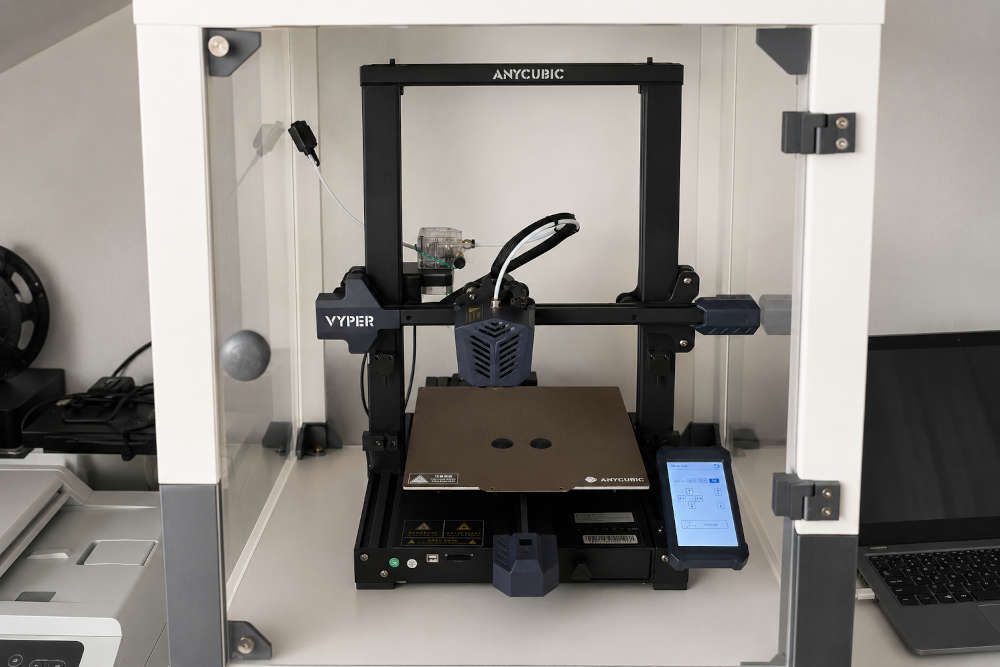
<p><a href="/assets/images/2026-08-30-Anycubic_Vyper/teaser.jpg" class="image-popup" title="My 3D printer &lt;i&gt;Anycubic Vyper&lt;/i&gt;. I built the enclosure myself using 3D-printed parts and side tables from IKEA." alt="My 3D printer &lt;i&gt;Anycubic Vyper&lt;/i&gt;. I built the enclosure myself using 3D-printed parts and side tables from IKEA.">
  <img class="align-center" src="/assets/images/2026-08-30-Anycubic_Vyper/teaser_th.jpg" title="My 3D printer &lt;i&gt;Anycubic Vyper&lt;/i&gt;. I built the enclosure myself using 3D-printed parts and side tables from IKEA." />
</a></p>

<p>I bought my first 3D printer in 2021 for around 350 euros: the <strong>Anycubic Vyper</strong>. The model was introduced in June 2021 and initially had a regular price of 359 US dollars (<a href="https://www.prnewswire.com/news-releases/anycubic-to-launch-vyper-a-fully-auto-leveling-fdm-3d-printer-that-innovates-the-3d-printing-workflow-301308999.html">Anycubic</a>). Since then, 3D printers have advanced significantly, particularly in terms of printing speed. For the Vyper, around 80 mm/s was recommended as a normal printing speed. A widely used printer today, such as the <a href="https://eu.store.bambulab.com/de/products/a1">Bambu Lab A1</a>, typically operates at around 200 to 300 mm/s in its standard profiles and can reach significantly higher speeds under suitable conditions. In one test, for example, the A1 needed just over 19 minutes for a <a href="https://www.3dbenchy.com/">3DBenchy</a>, a commonly used test model (<a href="https://www.tomshardware.com/3d-printing/bambu-lab-a1-review">Tom’s Hardware</a>). A smaller model that takes my Vyper around an hour can therefore, depending on its geometry, material, and quality settings, be finished on a modern printer in roughly 15 to 30 minutes. I still have my Vyper, however, because I only print very irregularly. Sometimes it runs for several days in a row, while at other times it is not switched on for weeks or even months. It becomes interesting to me whenever a problem suddenly arises for which there is no suitable solution available to buy.</p>

<h2 id="what-i-use-my-3d-printer-for">What I use my 3D printer for</h2>
<p>Of course, you can simply download ready-made models from the internet and print them. Platforms such as <a href="https://www.thingiverse.com/">Thingiverse</a> offer a huge selection of figures, mounts, spare parts, toys, and all kinds of more or less useful things. That is fun, but it was never the real appeal of 3D printing for me. It becomes interesting when I can solve a problem myself. A part is missing, something does not fit properly, or there is simply no suitable product for a very specific purpose. In that case, I can design the required component myself and hold it in my hands just a few hours later.</p>

<p>For example, I have already created a <strong>sound deflector for the television</strong>, an <strong>aerobridge for my bicycle</strong>, as well as various parts for our <strong>campervan</strong>, including screw covers and battery terminal covers.</p>

<p>For me, it is precisely these small parts that demonstrate the real value of a 3D printer. They are often highly specific and would either not be commercially available at all or would only be obtainable with a disproportionate amount of effort.</p>

<p>In the future, my own models will be collected under <a href="/en/activities/">Activities</a>. There, they can be viewed and also downloaded for personal use.</p>

<p>But how do you actually get from an idea to a finished plastic part?</p>

<h2 id="step-1-the-3d-model">Step 1: The 3D model</h2>
<p>Every print starts with a digital three-dimensional model.</p>

<p>You can either create one yourself or download an existing model. For my own designs, I use <a href="https://www.shapr3d.com/">Shapr3D</a>. The software is surprisingly intuitive for beginners. There is a limited free Basic version with restricted export options, as well as a paid Pro version that can be tested free of charge for 14 days (<a href="https://www.shapr3d.com/de-de/pricing">Shapr3D</a>).</p>

<p>The basic workflow is relatively simple: you first draw, for example, a rectangle or a circle with exact dimensions and then pull this two-dimensional shape into the third dimension. This creates a solid body. You can then cut out holes, round off edges, or add additional bodies.</p>

<p>After a short learning period, surprisingly complex parts can already be designed this way. There are also numerous explanatory videos and tutorials available for Shapr3D.</p>

<p>If you do not want to spend money on CAD software, there are also free alternatives, such as <a href="https://www.freecad.org/">FreeCAD</a>. And if you do not want to design anything yourself at all, you can find a large number of ready-made models on <a href="https://www.thingiverse.com/">Thingiverse</a> and similar platforms that can be used directly for 3D printing.</p>

<h2 id="step-2-the-right-filament">Step 2: The right filament</h2>
<p>Once you have a model, you still need the material it will be made from.</p>

<p>A classic FDM 3D printer such as my Anycubic Vyper uses plastic in the form of so-called <strong>filament</strong>. Put simply, this is a long plastic strand wound onto a spool. In many 3D printers for home use, this filament has a diameter of 1.75 millimeters.</p>

<p>There are many different plastics, each with different properties. I most commonly use <strong>PLA</strong> and <strong>PETG</strong>.</p>

<p><strong>PLA</strong> (polylactide) is particularly easy to print. It warps very little as it cools and produces clean print results. This makes it very suitable for beginners as well as for models and components that are not exposed to high mechanical or thermal loads. PLA is also usually made from renewable raw materials. The starting materials are plant-based sugars or starches, for example from corn, sugar cane, or sugar beets, which are first fermented into lactic acid and then further processed into plastic. PLA is therefore considered a bio-based plastic. Although it is in principle biodegradable or compostable, this mainly applies under the high temperatures and controlled conditions of industrial composting facilities. In a home compost or in the natural environment, by contrast, it degrades only very slowly.</p>

<p><strong>PETG</strong> (polyethylene terephthalate glycol) is tougher and more temperature-resistant and is therefore often better suited for functional components. However, during printing it has a somewhat greater tendency to form small plastic threads between individual areas, known as <em>stringing</em>. Overhangs are also often more difficult to print cleanly with PETG (<a href="https://help.prusa3d.com/de/article/petg_2059">Prusa</a>). PETG is a modified form of PET, which is also used, for example, in beverage bottles. Unlike PLA, PETG is usually made from fossil raw materials and is not biodegradable or compostable. It can in principle be recycled, although PETG print waste cannot be disposed of through conventional PET recycling streams everywhere.</p>

<p>Which material makes sense therefore depends on what the component will later need to withstand. A decorative object in the living room has different requirements from a mount on a bicycle or a component in a campervan.</p>

<h2 id="step-3-turning-the-model-into-printer-movements">Step 3: Turning the model into printer movements</h2>
<p>A 3D printer cannot initially do anything with the actual 3D model. Instead, it needs to know where the print head should move, how fast it should travel, how much plastic needs to come out of the nozzle, and when the next layer should begin.</p>

<p>This translation is handled by so-called <strong>slicer software</strong>. I use <a href="https://ultimaker.com/software/ultimaker-cura/">UltiMaker Cura</a>, a free and open-source program.</p>

<p>The term <em>slicer</em> comes from the English word <em>slice</em>. The software divides the three-dimensional model into many thin horizontal layers. From these layers, it then calculates the movements the printer has to perform. The result is usually a so-called <strong>G-code file</strong>.</p>

<p>Numerous parameters can be adjusted: layer height, printing speed, temperature, wall thickness, or how much of the inside of a component should be filled.</p>

<p>After all, a 3D-printed part does not have to be made entirely of solid plastic. Often, the outer wall consists of several solid layers, while the inside is filled only with a lattice-like structure known as <strong>infill</strong>. This saves material, weight, and printing time.</p>

<h2 id="step-4-onto-the-printer">Step 4: Onto the printer</h2>
<p>Once the model has been sliced, the generated file has to be transferred to the printer. With my Anycubic Vyper, for example, this is done using a memory card. Newer printers can often also receive files directly via Wi-Fi.</p>

<p>The desired filament is then loaded and the print is started.</p>

<p>Inside the print head is a heated nozzle. Depending on the plastic being used, the filament is typically heated there to temperatures of around 200 to 250 degrees Celsius. This makes it soft enough to be pushed through the small opening in the nozzle.</p>

<p>The nozzle deposits a thin line of plastic onto the print bed. Once the first layer is complete, the print head or the print bed moves a tiny distance in height. The next layer is then printed on top. And then the next one, and so on.</p>

<p>In this way, the finished three-dimensional component slowly emerges from hundreds or thousands of thin plastic layers. This also explains why even relatively small parts can take several hours. The printer really does build the object up layer by layer.</p>

<h2 id="the-problem-with-overhangs">The problem with overhangs</h2>
<p>At the same time, this method leads to one of the most important limitations of FDM 3D printing: the printer cannot simply print into thin air.</p>

<p>Each new plastic layer normally needs at least some material underneath it to rest on.</p>

<p>A vertical wall is therefore no problem. Sloped surfaces also work well up to a certain point. However, if a surface extends outward too steeply or part of the model begins completely in mid-air, the next plastic layer lacks the necessary support underneath.</p>

<p>As a rough guideline, many FDM printers can still print overhangs of around 45 to 60 degrees without additional support. How well this works, however, depends heavily on the printer, the material, the cooling, and the settings (<a href="https://help.prusa3d.com/article/modeling-with-3d-printing-in-mind_164135">Prusa</a>).</p>

<p>For more difficult overhangs, the slicer can automatically generate so-called <strong>support structures</strong>. This creates a kind of temporary plastic scaffold underneath the actual component. After printing, it is removed again.</p>

<p>When designing my own parts, I therefore try to consider how the component will later be positioned on the print bed while I am still modeling it. Sometimes it is enough to print a model the other way around or slightly change a shape in order to avoid large amounts of support material.</p>

<p>This is where you quickly realize that good 3D design is not only about making a component look right on the computer. When designing it, you should already take into account how it will actually be manufactured later.</p>]]></content><author><name>Matthias Munz</name></author><category term="3D Printing" /><summary type="html"><![CDATA[3D printing is no longer a technology reserved only for companies, research institutions, or ambitious hobbyists. The first comparatively affordable desktop 3D printers came onto the market in the late 2000s. One of the best-known early examples was the MakerBot CupCake CNC from 2009. At the time, it cost around 750 US dollars and was still supplied as a kit (Wired).]]></summary></entry><entry xml:lang="en"><title type="html">Quality control of my tellmeGen genome: Did I really receive 30× sequencing?</title><link href="https://matthiasmunz.de/en/Tellmegen_QC/" rel="alternate" type="text/html" title="Quality control of my tellmeGen genome: Did I really receive 30× sequencing?" /><published>2026-08-23T00:00:00+02:00</published><updated>2026-08-10T16:15:55+02:00</updated><id>https://matthiasmunz.de/Tellmegen_QC</id><content type="html" xml:base="https://matthiasmunz.de/Tellmegen_QC/"><![CDATA[<p>Recently, I <a href="/en/Sequencing_my_genome/">sequenced my own genome</a> with the direct-to-consumer whole-genome sequencing company <a href="https://www.tellmegen.com/">tellmeGen</a>. After downloading my genome and <a href="/en/Tellmegen_results_available/"> evaluating the tellmeGen reports</a>, one important question remained unanswered: <em>How good was the actual sequencing?</em></p>

<p>tellmeGen provided two large FASTQ files and a VCF containing the identified genetic variants, but no detailed sequencing quality report. I therefore processed the raw reads myself and evaluated their quality, mapping, duplication, coverage, and possible contamination.</p>

<p>The result is reassuring: <strong>my saliva sample produced a high-quality human whole-genome dataset, and tellmeGen reached the advertised 30× average coverage.</strong> I found no indication of a failed sequencing library, insufficient sequencing output, substantial non-human contamination, or contamination by DNA from another person.</p>

<p>The complete <a href="/en/assets/html/WGS-QC_multiqc_report_anonymized.html">anonymized MultiQC quality report</a> is available as an interactive HTML report.</p>

<h2 id="the-result-at-a-glance">The result at a glance</h2>

<table>
  <thead>
    <tr>
      <th>Quality metric</th>
      <th style="text-align: right">Result</th>
      <th>What it means</th>
      <th>Rating</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Sequencing output</td>
      <td style="text-align: right">720.0 million reads, 2 × 150 bp</td>
      <td>About 360 million read pairs and 108 billion sequenced bases</td>
      <td><strong>Very good</strong></td>
    </tr>
    <tr>
      <td>Bases with at least Q30</td>
      <td style="text-align: right">94.5%, about 102 Gb</td>
      <td>At least 99.9% estimated base-call accuracy for most bases</td>
      <td><strong>Excellent</strong></td>
    </tr>
    <tr>
      <td>Reads retained by fastp</td>
      <td style="text-align: right">100%</td>
      <td>No meaningful loss through quality or length filtering</td>
      <td><strong>Excellent</strong></td>
    </tr>
    <tr>
      <td>GC content</td>
      <td style="text-align: right">40.3%</td>
      <td>Appropriate for human whole-genome sequencing</td>
      <td><strong>Good</strong></td>
    </tr>
    <tr>
      <td>Reads mapped</td>
      <td style="text-align: right">99.2%</td>
      <td>Almost all reads could be aligned to the human reference genome</td>
      <td><strong>Excellent</strong></td>
    </tr>
    <tr>
      <td>Properly paired reads</td>
      <td style="text-align: right">96.1%</td>
      <td>Both ends usually aligned with the expected orientation and distance</td>
      <td><strong>Very good</strong></td>
    </tr>
    <tr>
      <td>Picard duplicate rate</td>
      <td style="text-align: right">1.1%</td>
      <td>Very little redundant sequencing after alignment</td>
      <td><strong>Excellent</strong></td>
    </tr>
    <tr>
      <td>Mean insert size</td>
      <td style="text-align: right">286 bp</td>
      <td>Normal fragment size for a 2 × 150-bp short-read library</td>
      <td><strong>Good</strong></td>
    </tr>
    <tr>
      <td>Final median depth</td>
      <td style="text-align: right">36×</td>
      <td>Half of the assessed positions had at least approximately this depth</td>
      <td><strong>Above target</strong></td>
    </tr>
    <tr>
      <td>Estimated autosomal mean depth</td>
      <td style="text-align: right">Approximately 34.4×</td>
      <td>Length-weighted average across chromosomes 1–22</td>
      <td><strong>Above target</strong></td>
    </tr>
    <tr>
      <td>Genome covered at least 10×</td>
      <td style="text-align: right">94%</td>
      <td>Most reference positions had substantial read support</td>
      <td><strong>Good</strong></td>
    </tr>
    <tr>
      <td>Genome covered at least 20×</td>
      <td style="text-align: right">Approximately 87%</td>
      <td>A large majority had strong coverage</td>
      <td><strong>Good</strong></td>
    </tr>
    <tr>
      <td>Genome covered at least 30×</td>
      <td style="text-align: right">73%</td>
      <td>Plausible for a genome averaging in the mid-30s</td>
      <td><strong>Good</strong></td>
    </tr>
    <tr>
      <td>VerifyBamID2 FREEMIX</td>
      <td style="text-align: right">0.000161754, or 0.016%</td>
      <td>No meaningful evidence of DNA from another human sample</td>
      <td><strong>Excellent</strong></td>
    </tr>
    <tr>
      <td>Indexcov coverage variation</td>
      <td style="text-align: right">15.3% of bins outside 0.85–1.15</td>
      <td>Some regional nonuniformity, relevant mainly to copy-number analysis</td>
      <td><strong>Minor caveat</strong></td>
    </tr>
    <tr>
      <td>Overall assessment</td>
      <td style="text-align: right">Approximately 34–36× high-quality human WGS</td>
      <td>The advertised average 30× coverage was reached</td>
      <td><strong>Good to very good</strong></td>
    </tr>
  </tbody>
</table>

<p>The measurements in this table come from the raw FASTQ, fastp, mark-duplicate BAM, final recalibrated BAM, Mosdepth, indexcov, and VerifyBamID2 sections of the analysis.</p>

<h2 id="reproducing-the-analysis">Reproducing the analysis</h2>

<p>I deposited the code, parameters, and cluster scripts in my public repository:</p>

<p><a href="https://github.com/matmu/wgs">https://github.com/matmu/wgs</a></p>

<p>For the main analysis, I used version 3.9.0 of <a href="https://nf-co.re/sarek/">nf-core/sarek</a>. Sarek is a community-developed workflow for processing whole-genome and exome sequencing data. It can take raw FASTQ files, align the reads to a reference genome, mark duplicate fragments, recalibrate base-quality values, call different types of genetic variants, annotate them, and generate quality-control reports (<a href="https://doi.org/10.12688/f1000research.16665.2">Garcia, <em>F1000Research</em>, 2020</a>).</p>

<p>Sarek is built with Nextflow. Instead of running the entire analysis as one monolithic program, Nextflow divides it into many smaller tasks. These tasks can run on a workstation, a computing cluster, or cloud infrastructure. Containers provide consistent versions of the required software, which makes the workflow easier to reproduce.</p>

<p>I used the GRCh38 human reference genome and BWA-MEM for alignment. My configuration was relatively extensive and included several callers for small variants, structural variants, and copy-number variants, followed by annotation with VEP and snpEff. A simpler workflow with only one small-variant caller would require fewer computing resources.</p>

<p>At the end, Sarek summarized the quality results in MultiQC. MultiQC combines outputs from many bioinformatics tools into one interactive report, making it easier to identify technical problems and compare different analysis stages (<a href="https://doi.org/10.1093/bioinformatics/btw354">Ewels, <em>Bioinformatics</em>, 2016</a>).</p>

<p>The tools represented in my report include:</p>

<ul>
  <li><strong>FastQC</strong>, which inspects the raw sequencing reads.</li>
  <li><strong>fastp</strong>, which performs read-level quality control and filtering (<a href="https://doi.org/10.1093/bioinformatics/bty560">Chen, <em>Bioinformatics</em>, 2018</a>).</li>
  <li><strong>samtools</strong>, which summarizes the alignments.</li>
  <li><strong>Picard MarkDuplicates</strong>, which estimates alignment-based library duplication.</li>
  <li><strong>Mosdepth</strong>, which calculates genome-wide sequencing depth and coverage distributions (<a href="https://doi.org/10.1093/bioinformatics/btx699">Pedersen, <em>Bioinformatics</em>, 2018</a>).</li>
  <li><strong>indexcov</strong>, which rapidly screens for regional coverage abnormalities and large copy-number changes (<a href="https://doi.org/10.1093/gigascience/gix090">Pedersen, <em>GigaScience</em>, 2017</a>).</li>
</ul>

<h2 id="how-much-computing-power-was-required">How much computing power was required?</h2>

<p>Whole-genome analysis needs much more storage than the compressed FASTQ files initially suggest. Reads are decompressed, aligned, sorted, recalibrated, divided into genomic regions, and processed by several variant callers. Nextflow also retains intermediate files so that an interrupted analysis can be continued with <code class="language-plaintext highlighter-rouge">-resume</code> instead of starting again.</p>

<p>My analysis used the following storage:</p>

<table>
  <thead>
    <tr>
      <th>Directory or data type</th>
      <th style="text-align: right">Storage used</th>
      <th>What it contains</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Original compressed FASTQ files</td>
      <td style="text-align: right">Approximately 83 GB</td>
      <td>Raw paired-end sequencing reads</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">work/</code></td>
      <td style="text-align: right">793 GB</td>
      <td>Nextflow intermediate files required for resuming tasks</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">results/</code></td>
      <td style="text-align: right">401 GB</td>
      <td>Final Sarek and VerifyBamID2 results, including archives</td>
    </tr>
    <tr>
      <td><code class="language-plaintext highlighter-rouge">cache/</code></td>
      <td style="text-align: right">39 GB</td>
      <td>Reference data and software containers</td>
    </tr>
    <tr>
      <td><strong>Approximate total</strong></td>
      <td style="text-align: right"><strong>1.32 TB</strong></td>
      <td>Complete analysis directory at the time of measurement</td>
    </tr>
  </tbody>
</table>

<p>The results directory contained both unpacked files and compressed archives, including a 90 GB Sarek archive and a 43 GB VerifyBamID2 archive. Some of the 401 GB was therefore intentional duplication rather than unique output.</p>

<p>For a similarly broad analysis, I would start with <strong>at least 1.5 TB of free storage</strong>. A 2 TB working volume is safer, particularly when intermediate files, references, archives, and several variant callers are retained. Fast local SSD or NVMe storage is preferable because alignment and variant calling involve substantial disk input and output.</p>

<p>The Nextflow coordinator itself ran with 16 GB of memory, but it only organized the workflow. The actual analysis tasks were submitted separately. In my configuration, DeepVariant requested 32 GB, GATK MarkDuplicates requested 64 GB, and Varlociraptor initially requested 64 GB with the option to request more after a failed attempt.</p>

<p>For a single workstation or server, <strong>approximately 128 GB of RAM and 8 to 16 CPU cores</strong> would be a comfortable configuration for this broad multi-caller workflow. A system with 64 GB may still work if concurrent tasks are restricted and some optional, memory-intensive callers are disabled.</p>

<p>A suitable machine does not have to be owned. A virtual or dedicated server can also be rented. I have personally had good experiences with <a href="https://contabo.com/">Contabo</a>, although this is not a sponsored recommendation. For this workload, the smallest standard VPS would not be appropriate. The important requirements are sufficient memory, around 2 TB of working storage, and reasonable disk performance.</p>

<p>A whole genome is uniquely identifying personal data. On a rented server, access should be restricted, SSH keys should be used, storage and backups should be encrypted where possible, and files that are no longer needed should be deleted.</p>

<h2 id="what-does-30-coverage-actually-mean">What does 30× coverage actually mean?</h2>

<p>Sequencing depth describes how many reads overlap a position in the reference genome. A depth of 30× does <strong>not</strong> mean that every position is covered by exactly 30 reads. It means that the average coverage across the genome is approximately 30 reads per position.</p>

<p>This distinction matters. tellmeGen now describes its product as whole-genome sequencing with an <strong>average coverage of 30×</strong>, meaning that positions are read about 30 times on average (<a href="https://shop.tellmegen.com/en-us/blogs/before-buying/what-is-tellmegens-ultra-wgs-30x-dna-test-what-does-it-include-and-what-information-does-it-provide">tellmeGen, 2026</a>).</p>

<p>Some genomic positions inevitably receive more reads and others fewer. The distribution is affected by random sampling, GC content, repetitive DNA, the uniqueness of a sequence, and how well short reads can be aligned to the reference genome.</p>

<p>My two FASTQ files each contained approximately 360 million reads with a read length of 150 bases. Together, they contained approximately 720 million individual reads, corresponding to about 360 million read pairs.</p>

<p>The total raw sequence yield was therefore:</p>

<p><strong>720 million reads × 150 bases = 108 billion bases, or 108 Gb</strong></p>

<p>Dividing this by a haploid human genome size of approximately 3.1 to 3.2 billion bases gives a theoretical raw depth of about <strong>34 to 35×</strong>. This calculation already suggested that tellmeGen had generated enough data for a nominal 30× genome.</p>

<p>The processed coverage measurements confirm it more directly. The final recalibrated sample had a <strong>median depth of 36×</strong>, and the length-weighted mean across chromosomes 1–22 was approximately <strong>34.4×</strong>.</p>

<h2 id="did-tellmegen-deliver-the-promised-30">Did tellmeGen deliver the promised 30×?</h2>

<p><strong>Yes.</strong></p>

<p>The estimated autosomal mean of approximately 34.4× is above tellmeGen’s advertised average of 30×. The final median depth of 36× independently supports the same conclusion.</p>

<p>The cumulative Mosdepth coverage was approximately:</p>

<table>
  <thead>
    <tr>
      <th style="text-align: right">Minimum depth</th>
      <th style="text-align: right">Proportion of reference positions</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td style="text-align: right">At least 1×</td>
      <td style="text-align: right">95%</td>
    </tr>
    <tr>
      <td style="text-align: right">At least 5×</td>
      <td style="text-align: right">94%</td>
    </tr>
    <tr>
      <td style="text-align: right">At least 10×</td>
      <td style="text-align: right">94%</td>
    </tr>
    <tr>
      <td style="text-align: right">At least 20×</td>
      <td style="text-align: right">Approximately 87%</td>
    </tr>
    <tr>
      <td style="text-align: right">At least 30×</td>
      <td style="text-align: right">73%</td>
    </tr>
    <tr>
      <td style="text-align: right">At least 50×</td>
      <td style="text-align: right">2%</td>
    </tr>
  </tbody>
</table>

<p>It may initially seem contradictory that the genome averaged approximately 34.4× while only 73% of reference positions reached at least 30×. It is not a contradiction.</p>

<p>An average describes the entire distribution. Positions above 30× can compensate mathematically for positions below 30×. Even a technically excellent short-read genome will contain both highly covered and weakly covered regions.</p>

<p>Mosdepth’s cumulative percentage also uses the assessed reference bases as its denominator. Depending on the reference and analysis settings, this can include reference gaps, repetitive regions, centromeric sequence, and other positions that are difficult or impossible to map with 150-base reads. The approximately 5–6% without substantial coverage should therefore not automatically be interpreted as 5–6% of useful or clinically callable DNA being absent.</p>

<p>A callable-genome analysis would provide a more specific answer by excluding unsuitable reference regions and requiring minimum mapping quality, base quality, and genotype quality.</p>

<h2 id="coverage-across-individual-chromosomes">Coverage across individual chromosomes</h2>

<p>Most autosomes had average depths of approximately 31–37×. Chromosome 22 was lower at about 25.4×, while chromosomes 14 and 15 were around 29.6×.</p>

<p>These chromosomes contain large repetitive and difficult-to-map regions. The lower chromosome-wide averages are therefore worth observing, but they do not indicate that an entire chromosome failed. There was <strong>no chromosome-wide dropout</strong>.</p>

<p>For medically interesting variants, the genome-wide average is not sufficient. The relevant locus should be checked individually for read depth, genotype quality, mapping quality, strand balance, and local mappability.</p>

<h2 id="raw-base-quality-was-excellent">Raw base quality was excellent</h2>

<p>The raw sequencing reads were high quality:</p>

<ul>
  <li>Read 1 had mean per-cycle quality values around Q35–36 and ended at approximately Q34.8.</li>
  <li>Read 2 started around Q36 and ended at approximately Q34.0.</li>
  <li>94.5% of all bases, about 102 Gb, had a quality score of at least Q30.</li>
  <li>The proportion of undetermined <code class="language-plaintext highlighter-rouge">N</code> bases was effectively zero.</li>
  <li>No meaningful adapter or overrepresented-sequence problem was detected.</li>
  <li>fastp retained 100% of reads to the precision displayed in the report.</li>
</ul>

<p>A Q30 base has an estimated error probability of 0.1%, or about one incorrect base call per 1,000 calls. Q35 corresponds to an even lower estimated error probability. Quality values above Q30 across almost the entire 150-base read are therefore a strong result.</p>

<p>As is common with Illumina sequencing, the quality declined slightly toward the end of Read 2, but the final values remained very high. There is no indication of a problematic end-of-read quality collapse.</p>

<h2 id="the-two-fastqc-warnings">The two FastQC warnings</h2>

<p>FastQC marked two warning categories for both reads:</p>

<ul>
  <li><strong>Per-base sequence content</strong></li>
  <li><strong>Per-sequence GC content</strong></li>
</ul>

<p>A warning is not the same as a failed sequencing run. FastQC applies general statistical expectations, and some technically acceptable libraries trigger warnings because they do not perfectly match its model.</p>

<h3 id="per-base-sequence-content">Per-base sequence content</h3>

<p>The first approximately eight sequencing cycles showed an imbalance between A, C, G, and T. After these initial positions, the composition became very stable, with A and T each around 30% and G and C each around 20%.</p>

<p>The <a href="https://www.bioinformatics.babraham.ac.uk/projects/fastqc/Help/3%20Analysis%20Modules/4%20Per%20Base%20Sequence%20Content.html">FastQC documentation for per-base sequence content</a> explains that the module checks whether nucleotide proportions behave as expected across read positions. In this sample, the deviation is limited mainly to the first few bases. Combined with the excellent base quality, mapping rate, and lack of adapter or overrepresented-sequence problems, this pattern looks like mild initial-cycle or library-preparation bias rather than widespread bad sequencing.</p>

<h3 id="per-sequence-gc-content">Per-sequence GC content</h3>

<p>The overall GC content was 40.3%, and the distribution peaked around 38–39%. This is appropriate for a human whole-genome library.</p>

<p>The observed distribution differed enough from FastQC’s modelled normal curve to trigger a warning. However, there was no strong second peak, no substantial reduction in human mapping, and no overrepresented sequence signal. The <a href="https://www.bioinformatics.babraham.ac.uk/projects/fastqc/Help/3%20Analysis%20Modules/5%20Per%20Sequence%20GC%20Content.html">FastQC documentation for per-sequence GC content</a> notes that the module compares the observed distribution with a theoretical model. A warning alone does not establish contamination.</p>

<p>I therefore classify both FastQC findings as <strong>minor warnings, not reasons for concern</strong>.</p>

<h2 id="mapping-and-library-quality">Mapping and library quality</h2>

<p>After alignment, <strong>99.2% of reads mapped to the human reference genome</strong>. Only about 0.8% were unmapped before later BAM filtering.</p>

<p>This is an excellent mapping rate and shows that the overwhelming majority of reads behaved like human genomic DNA. It also argues against a substantial fraction of bacterial, food-derived, or other obviously non-human DNA in the saliva library.</p>

<p>The properly paired rate was <strong>96.1%</strong>. This means that both ends of most DNA fragments aligned in the expected orientation and at a plausible distance from each other. Together with the <strong>286-bp mean insert size</strong>, this supports a well-constructed short-read library.</p>

<h2 id="why-do-the-duplicate-estimates-look-inconsistent">Why do the duplicate estimates look inconsistent?</h2>

<p>The report contains three different duplication estimates:</p>

<table>
  <thead>
    <tr>
      <th>Tool</th>
      <th style="text-align: right">Estimated duplication</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>FastQC</td>
      <td style="text-align: right">Approximately 12.1–12.2%</td>
    </tr>
    <tr>
      <td>fastp</td>
      <td style="text-align: right">4.3%</td>
    </tr>
    <tr>
      <td>Picard MarkDuplicates</td>
      <td style="text-align: right">1.1%</td>
    </tr>
  </tbody>
</table>

<p>These values are not directly comparable because the tools use different algorithms and definitions.</p>

<p>FastQC and fastp estimate duplication from read sequences before using their genomic alignment positions. Naturally repeated parts of the human genome and reads that happen to start with the same sequence can therefore contribute to these estimates.</p>

<p>Picard assesses duplicate fragments after alignment. It uses mapping positions and pairing information to identify reads that probably originated from the same original DNA molecule because of PCR amplification or optical duplication. For downstream variant calling, this alignment-based estimate is the most relevant of the three.</p>

<p>The <strong>1.1% Picard duplicate rate is excellent</strong>. It suggests that the large sequencing yield came from a highly diverse collection of original DNA fragments rather than repeated sequencing of a small library.</p>

<h2 id="did-the-saliva-sample-cause-contamination">Did the saliva sample cause contamination?</h2>

<p>Saliva samples can contain bacterial DNA, food-derived DNA, and DNA from other non-human sources. In this dataset, there is no obvious sign that such material compromised the sequencing:</p>

<ul>
  <li>99.2% of reads mapped to the human reference.</li>
  <li>GC content was appropriate for human WGS.</li>
  <li>There was no large unusual secondary GC peak.</li>
  <li>No meaningful overrepresented-sequence problem was detected.</li>
</ul>

<p>These observations strongly suggest that non-human DNA was not a major fraction of the library. They are not, however, a formal taxonomic analysis of the unmapped reads.</p>

<p>Mapping statistics also cannot detect DNA from another human. Reads from another person would still align well to the human reference genome. I therefore ran VerifyBamID2, which estimates human-to-human contamination from allele patterns while accounting for genetic ancestry (<a href="https://doi.org/10.1101/gr.246934.118">Zhang, <em>Genome Research</em>, 2020</a>).</p>

<p>The main result was:</p>

<div class="language-text highlighter-rouge"><div class="highlight"><pre class="highlight"><code>FREEMIX = 0.000161754
</code></pre></div></div>

<p>Expressed as a percentage:</p>

<p><strong>0.000161754 × 100 = 0.0162%</strong></p>

<p>This is effectively zero for practical quality-control purposes. I found <strong>no meaningful evidence that the sample contained DNA from another person</strong>.</p>

<p>VerifyBamID2 also reported principal-component coordinates for an “intended sample” and a hypothetical “contaminating sample.” These coordinates describe positions in an ancestry-related statistical space. They are not contamination percentages. Because the estimated contaminating fraction is essentially zero, the coordinates of the hypothetical contaminant should not be interpreted as evidence that a second person was actually present.</p>

<h2 id="one-caveat-regional-coverage-uniformity">One caveat: regional coverage uniformity</h2>

<p>The indexcov summary reported approximately:</p>

<ul>
  <li><strong>6.6% of bins with normalized depth below 0.15</strong></li>
  <li><strong>15.3% of bins outside the normalized 0.85–1.15 range</strong></li>
</ul>

<p>Indexcov estimates coverage in large genomic bins and is intended to highlight missing regions, broad coverage bias, aneuploidies, and large deletions or duplications (<a href="https://doi.org/10.1093/gigascience/gix090">Pedersen, <em>GigaScience</em>, 2017</a>).</p>

<p>The low-depth-bin proportion broadly agrees with the difficult or uncovered part of the reference seen in Mosdepth. The out-of-range proportion indicates some regional variation in coverage. Because this report contains only one sample, there is no sequencing cohort available for comparison.</p>

<p>I consider this worth noting, particularly for copy-number and structural-variant analysis, but <strong>not an obvious red flag</strong>. The overall mapping, depth, pairing, base-quality, and duplication statistics are strong, and there is no chromosome-wide dropout.</p>

<h2 id="what-this-quality-report-cannot-guarantee">What this quality report cannot guarantee</h2>

<p>A good genome-wide quality report does not make every individual result correct.</p>

<p>Short reads remain less reliable in repetitive sequences, segmental duplications, pseudogenes, and genes with closely related copies. Genome in a Bottle benchmarking has shown that hundreds of medically relevant genes contain regions that are difficult to assess with conventional short-read methods (<a href="https://doi.org/10.1038/s41587-021-01158-1">Wagner, <em>Nature Biotechnology</em>, 2022</a>).</p>

<p>For an individual variant, I would therefore still inspect:</p>

<ul>
  <li>local read depth,</li>
  <li>genotype quality,</li>
  <li>mapping quality,</li>
  <li>allele balance and strand balance,</li>
  <li>nearby repeats or duplicated genes,</li>
  <li>agreement between variant callers,</li>
  <li>and external population and clinical databases.</li>
</ul>

<p>A separate fingerprint or comparison with an independently obtained sample would also be required to prove sample identity. VerifyBamID2 shows that the dataset does not look like a mixture, but it cannot prove that the sample belongs to a particular named person without a reference genotype.</p>

<p>The results should not be treated as equivalent to a validated clinical diagnostic test. A medically important finding should be reviewed carefully and, where appropriate, confirmed by an accredited diagnostic laboratory.</p>

<h2 id="conclusion">Conclusion</h2>

<p>The tellmeGen sequencing appears to be <strong>genuinely good-quality human whole-genome sequencing at approximately 34–36× depth</strong>.</p>

<p>The main findings are:</p>

<ul>
  <li>no major base-quality problem,</li>
  <li>sufficient raw sequencing output,</li>
  <li>94.5% of bases at Q30 or better,</li>
  <li>99.2% human mapping,</li>
  <li>good paired-read behavior,</li>
  <li>exceptionally low alignment-based duplication,</li>
  <li>no obvious substantial non-human contamination,</li>
  <li>effectively zero estimated human cross-sample contamination,</li>
  <li>and average coverage clearly above the advertised 30×.</li>
</ul>

<p>The important qualification is that <strong>30× average coverage does not mean that every genomic position is covered 30 times</strong>. About 73% of the full assessed reference reached at least 30×, while difficult, repetitive, and poorly mappable regions remained less well covered. This is expected for short-read WGS and does not contradict the 34.4× estimated autosomal mean.</p>

<p>There is therefore no general quality issue that would prevent further analysis. For medically interesting variants, region-specific depth, genotype quality, and mappability remain essential.</p>

<p>My next step will be to calculate polygenic scores using the <a href="https://www.pgscatalog.org/">Polygenic Score Catalog</a>. The catalog provides published score definitions, including variants, alleles, weights, and curated metadata needed for reproducible application (<a href="https://doi.org/10.1038/s41588-021-00783-5">Lambert, <em>Nature Genetics</em>, 2021</a>). Its <a href="https://github.com/PGScatalog/pgsc_calc">PGS Catalog Calculator</a> supports reproducible score calculation and ancestry-aware normalization (<a href="https://doi.org/10.1038/s41588-024-01937-x">Lambert, <em>Nature Genetics</em>, 2024</a>).</p>

<p>A polygenic score is not a diagnosis. It summarizes genetic predisposition relative to an appropriate reference population, and its interpretation depends on ancestry, calibration, the underlying study, and how much of the phenotype the score can actually predict. Nevertheless, calculating these scores from my own whole-genome data will be an interesting next step in exploring what personal genomic data can, and cannot, tell me.</p>]]></content><author><name>Matthias Munz</name></author><category term="Bioinformatics" /><summary type="html"><![CDATA[Recently, I sequenced my own genome with the direct-to-consumer whole-genome sequencing company tellmeGen. After downloading my genome and evaluating the tellmeGen reports, one important question remained unanswered: How good was the actual sequencing?]]></summary></entry><entry xml:lang="en"><title type="html">When AI Takes Over Work: Will Ownership Become More Important Than Money?</title><link href="https://matthiasmunz.de/en/ChatWithGPT_KI_Geld_Eigentum/" rel="alternate" type="text/html" title="When AI Takes Over Work: Will Ownership Become More Important Than Money?" /><published>2026-08-16T00:00:00+02:00</published><updated>2026-08-18T21:39:22+02:00</updated><id>https://matthiasmunz.de/ChatWithGPT_KI_Geld_Eigentum</id><content type="html" xml:base="https://matthiasmunz.de/ChatWithGPT_KI_Geld_Eigentum/"><![CDATA[<p>In an interview with <em>The Economist</em> in July 2026, Elon Musk made a remarkable prediction: <strong>“Money won’t matter in 2036.”</strong> In other words, money will no longer play a significant role in just ten years (<a href="https://www.youtube.com/watch?v=XuoqKYxDHVc">The Economist, Interview with Elon Musk</a>).</p>

<p>At first glance, the reasoning behind this seems quite plausible. If artificial intelligence can take over virtually all mental work and humanoid robots can do the same for physical labor, goods and services could be produced with very little human labor. Labor would drastically lose its importance as a factor of production. Production would become cheaper, prosperity would increase, and many things that are expensive today could eventually be available almost for free.</p>

<p>But does this really mean that money will disappear?</p>

<p>Probably not.</p>

<p>The more interesting consequence might be another: <strong>If human labor becomes less valuable, property could simultaneously become more important.</strong></p>

<h2 id="disclaimer">Disclaimer</h2>
<p>In my blog series “Chat with GPT”, I ask <a href="https://www.chatgpt.com">ChatGPT</a> on a variety of topics, from world politics to everyday issues, to get concise summaries and answers. The answers provided by ChatGPT are generated from large datasets, which may include biases, for example from Western perspectives. While the model strives for accuracy, it can sometimes produce incorrect or misleading information. I do not take responsibility for the validity of the content. Though I aim to ensure that the answers reflect common sense, I encourage you to cross-check facts and verify information through trusted sources. You are also welcome to reach out to me with suggestions for improvement.</p>

<h2 id="what-musk-actually-means">What Musk Actually Means</h2>

<p>Musk’s thesis is based on the idea of a nearly fully automated economy. In this scenario, AI doesn’t just take on tasks such as programming, translation, accounting, or medical diagnostics. Robots also transfer this intelligence to the physical world. They build houses, produce food, repair machines, transport goods, and may eventually even take over caregiving, cleaning, and large parts of the skilled trades.</p>

<p>This would amplify a trend already evident in many digital products: the marginal cost of an additional unit can be very low.</p>

<p>An additional copy of software costs practically nothing. AI services can also be scaled up significantly, though not for free, since computing power and energy still incur costs. A fully automated factory could manufacture products with an ever-decreasing amount of human labor.</p>

<p>Musk therefore speaks of a kind of “quasi-infinite economy”: an economy in which AI and robotics are expected to produce goods and services in very large quantities (<a href="https://www.youtube.com/watch?v=XuoqKYxDHVc">The Economist</a>).</p>

<p>In a world like that, the question does indeed arise: Why do we still work, and why do we still need money?</p>

<p>The key point, however, is this: <strong>Automation can greatly reduce the need for human labor. It does not automatically eliminate scarcity.</strong></p>

<h2 id="ai-could-actually-make-intellectual-work-very-inexpensive">AI Could Actually Make Intellectual Work Very Inexpensive</h2>

<p>In the realm of digital work, this trend is already evident today.</p>

<p>Generative AI can write texts, develop software, analyze data, generate images, review contracts, summarize scientific literature, or answer customer inquiries. It still often requires human oversight. But this boundary is shifting at an astonishing rate.</p>

<p>The research organization METR attempts to measure this development using what are known as <em>Task Completion Time Horizons</em>. This involves examining how long it takes a human expert to complete a task that an AI agent can already solve independently with a certain level of reliability.</p>

<p>In recent years, this time span has increased exponentially in the benchmarks studied. METR initially found that the time roughly doubled every seven months; in some software, mathematics, and scientific benchmarks, even shorter doubling times were observed at times (<a href="https://metr.org/blog/2025-03-19-measuring-ai-ability-to-complete-long-tasks/">METR, <em>Measuring AI Ability to Complete Long Tasks</em></a> ; <a href="https://metr.org/time-horizons/">current time-horizon data</a>). However, METR explicitly warns against directly applying these benchmarks to entire professions: The tasks are predominantly drawn from software development, machine learning, and cybersecurity and are more clearly defined than many activities in the real working world. However, METR expressly cautions against directly applying these benchmarks to entire professions: The tasks are primarily drawn from software development, machine learning, and cybersecurity, and are more clearly defined than many activities in the real working world. Nevertheless, the data show that AI is increasingly capable of handling longer, continuous tasks independently.</p>

<p>In a comprehensive analysis from 2025, the International Labor Organization (ILO) concludes that approximately 24 percent of jobs worldwide are at least partially exposed to generative AI. In high-income countries, this figure stands at 34 percent. This is an estimate of the technical potential for exposure, not of automation that has already taken place (<a href="https://www.ilo.org/publications/generative-ai-and-jobs-refined-global-index-occupational-exposure">ILO &amp; NASK, <em>Generative AI and Jobs: A Refined Global Index of Occupational Exposure</em></a>).</p>

<p>What is noteworthy, however, is the ILO’s interpretation: <strong>Transformation is currently far more likely than complete replacement.</strong></p>

<p>So an accountant will not necessarily disappear, but might need significantly less time to do the same work. A software team could achieve the same results with fewer people using powerful AI agents. A lawyer can have large volumes of documents pre-sorted and analyzed much more quickly.</p>

<p>This is precisely where the first major change is likely to take place.</p>

<h2 id="a-possible-scenario-by-2030-ai-becomes-a-regular-coworker">A Possible Scenario by 2030: AI Becomes a Regular Coworker</h2>

<p>For the second half of the 2020s, it seems plausible that AI will initially take over large portions of routine digital work.</p>

<p>Research, translation, standard programming, documentation, customer service, marketing, administrative tasks, parts of accounting, and many analytical tasks can increasingly be automated.</p>

<p>This does not necessarily mean that millions of people will become unemployed within a few years. A productivity boost is more likely at first: With AI, one person can do the work that previously required several people.</p>

<p>The immediate effect, therefore, might consist less of spectacular mass layoffs and more of something less conspicuous: companies hiring fewer people.</p>

<p>Entry-level positions, in particular, could be affected. The very tasks through which young employees have traditionally gained experience are often relatively easy to automate.</p>

<p>This marks the beginning of a trend whose economic consequences could be significantly greater than they initially appear.</p>

<h2 id="a-possible-scenario-for-the-early-2030s-from-individual-tasks-to-entire-workflows">A Possible Scenario for the Early 2030s: From Individual Tasks to Entire Workflows</h2>

<p>The next step is crucial.</p>

<p>Today, we mostly use AI as a tool. We ask a question, verify the answer, and then continue working.</p>

<p>Future AI agents, on the other hand, could pursue goals independently: gathering information, preparing decisions, operating software, coordinating other AI systems, and monitoring results.</p>

<p>A tool is thus increasingly becoming a digital employee.</p>

<p>If this step is successful, automation will no longer affect only individual tasks within a profession. Entire process chains can be automated.</p>

<p>Then, for example, accounting, insurance processing, parts of administration, software development, or technical documentation could function with a fraction of today’s workforce.</p>

<p>However, the speed at which this will happen is highly controversial in scientific circles.</p>

<p>A survey of 2,778 AI researchers conducted in 2023 and published in 2025 found that respondents estimated a median probability of 50 percent that machines could outperform humans in virtually all tasks by around 2047. By contrast, the corresponding 50 percent threshold for the complete automation of all human occupations was not reached until 2116 (<a href="https://www.jair.org/index.php/jair/article/view/19087">Grace et al., <em>Thousands of AI Authors on the Future of AI</em></a>).</p>

<p>The difference between these two figures is revealing.</p>

<p><strong>Automating intelligence is not the same as automating the economy.</strong></p>

<h2 id="robotics-is-the-more-challenging-step">Robotics Is the More Challenging Step</h2>

<p>That is precisely why Musk’s integration of AI and robotics is so important.</p>

<p>Today, an AI model can analyze a complex text in seconds. But replacing a faucet in an unfamiliar old building, tidying up a messy kitchen, or responding flexibly to unexpected situations on a construction site is much more difficult for a robot.</p>

<p>The physical world is unstructured.</p>

<p>Nevertheless, robotics is also advancing rapidly. According to the International Federation of Robotics, approximately 542,000 new industrial robots were installed worldwide in 2024 alone. That was more than twice as many as ten years earlier (<a href="https://ifr.org/worldrobotics/report-2025">IFR, <em>World Robotics 2025 – Industrial Robots</em></a>).</p>

<p>However, these machines operate primarily in highly controlled environments.</p>

<p>The big leap forward would be an affordable, general-purpose robot that not only performs precisely programmed movements but can also flexibly handle a variety of tasks.</p>

<p>If this breakthrough is achieved, significantly more physical tasks could be automated in the 2030s and 2040s.</p>

<p>Manufacturing, warehousing, agriculture, and logistics are likely to be automated more quickly than skilled trades, caregiving, or work in changing and unpredictable environments.</p>

<p>It is not possible to give a precise year for this with any certainty. But it is precisely at this point that it will be decided whether AI will merely be another major productivity revolution or actually mark the beginning of a fundamentally different economic order.</p>

<h2 id="what-happens-when-labor-costs-almost-nothing">What happens when labor costs almost nothing?</h2>

<p>Let’s take Musk’s scenario seriously for a moment.</p>

<p>A company manufactures a refrigerator. Today, this process involves human labor throughout a long chain: raw materials are extracted, components are produced, appliances are assembled, factories are operated, goods are transported, sold, and repaired.</p>

<p>If, at some point, nearly every one of these steps can be handled by machines, labor costs will drop dramatically.</p>

<p>The same applies to many services.</p>

<p>An AI tutor could provide individualized tutoring to every child. An AI system could analyze medical data. Software could be developed for practically no cost. A robot could clean the house.</p>

<p>As a result, a significant portion of our current consumption could indeed become extremely cheap.</p>

<p>But not everything.</p>

<h2 id="the-crucial-question-isnt-about-labor-but-about-scarcity">The crucial question isn’t about labor, but about scarcity</h2>

<p>Suppose robots can build houses at virtually no cost.</p>

<p>Then, in theory, they could construct millions of houses.</p>

<p>But they can’t produce a second plot of land right on Lake Starnberg.</p>

<p>This is precisely where the problem with Musk’s thesis lies.</p>

<p>Money doesn’t exist just because people have to be paid for their work. Money and prices also fulfill another fundamental function: <strong>They help coordinate and allocate scarce resources.</strong></p>

<p>Let’s imagine ten particularly attractive houses on a lake. At the same time, ten thousand people want to live there.</p>

<p>Even if building the houses costs nothing, land remains scarce.</p>

<p>Some mechanism must determine who gets it.</p>

<p>People could draw lots. The government could allocate it. There could be waiting lists.</p>

<p>Or people could bid against each other.</p>

<p>Then something emerges that, economically speaking, functions almost exactly like money.</p>

<p>As long as different people want to own or use the same scarce resources, a pricing or allocation mechanism will likely remain necessary even in a highly automated economy.</p>

<h2 id="material-assets-do-not-automatically-retain-their-value">Material Assets Do Not Automatically Retain Their Value</h2>

<p>At first glance, one might conclude that material things are generally becoming more important.</p>

<p>However, it’s not that simple.</p>

<p>Even raw materials may become less scarce due to new extraction methods, recycling, or substitution. Agricultural land could lose relative importance if precision farming, autonomous machinery, new breeding methods, or indoor farming massively increase productivity.</p>

<p>Even a house consists largely of reproducible materials.</p>

<p>If robots eventually become capable of constructing buildings very cheaply, the real value of the structure could even decline.</p>

<p>The non-reproducible part is, rather, the land itself—and especially its location.</p>

<p>Therefore, the distinction between digital and material would not be the decisive factor.</p>

<p>What would be decisive is:</p>

<p><strong>What will remain scarce?</strong></p>

<h2 id="property-could-become-more-important-than-work">Property Could Become More Important Than Work</h2>

<p>And this gives rise to a much more far-reaching consequence.</p>

<p>For many people today, the ability to exchange work for income over decades is their most important economic asset.</p>

<p>They do not necessarily own large factories, land, or businesses. Their income therefore depends largely on their own labor.</p>

<p>A highly automated economy changes precisely this relationship.</p>

<p>If a machine can perform the same task more cheaply, human labor loses relative economic value.</p>

<p>But the machine itself belongs to someone.</p>

<p>As a result, income tends to shift from labor as a factor of production to capital as a factor of production.</p>

<p>Daron Acemoglu and Pascual Restrepo use historical U.S. data to show that automation may have contributed significantly to increased wage inequality between groups since 1980. In their model, the effects of automation account for about 52 percent of the increase in this <em>between-group inequality</em>; this cannot simply be applied to AI, but it underscores how strongly the distributional effects of automation depend on labor market and property structures (<a href="https://www.nber.org/papers/w32536">Acemoglu &amp; Restrepo, <em>Automation and Rent Dissipation</em></a>).</p>

<p>In a fully automated factory, it may eventually no longer matter who works there.</p>

<p>What matters is <strong>who owns the factory</strong>.</p>

<p>The same applies to robots, data centers, energy production, infrastructure, and AI systems.</p>

<p>The socially crucial question of the AI revolution might therefore eventually not be:</p>

<p><strong>What kind of job do you have?</strong></p>

<p>But rather:</p>

<p><strong>What do you own?</strong></p>

<h2 id="does-this-mean-you-should-buy-real-estate-now">Does this mean you should buy real estate now?</h2>

<p>This line of thinking almost inevitably leads to the question of real estate.</p>

<p>If human labor becomes relatively less important while scarce assets remain, it seems logical at first glance to convert earned income into property as early as possible.</p>

<p>There is certainly a rational argument to be made here.</p>

<p>But it does not follow that every piece of real estate is automatically a good hedge against the AI revolution.</p>

<p>Economically speaking, a piece of real estate consists of at least two very different components: the building and the land.</p>

<p>The building itself is, in principle, reproducible. Robotics could even significantly reduce construction costs in the long term.</p>

<p>The plot of land is not.</p>

<p>A world with extremely cheap automated production could therefore, paradoxically, make the difference between good and bad locations even more pronounced.</p>

<p>If a house can be built for a fraction of today’s cost, what’s on it becomes less important. <strong>Where it stands</strong> could become all the more important.</p>

<p>An attractive location in an economically strong region, with access to nature, infrastructure, or a sought-after city, cannot be replicated at will.</p>

<p>This generally suggests that certain forms of real estate ownership could remain relatively valuable in an automated economy.</p>

<p>However, it does not mean you should buy real estate at any cost.</p>

<p>Demographics, regulation, taxes, financing costs, and regional appeal will not disappear just because of AI. A heavily mortgaged property in a shrinking region is something entirely different from scarce land in a location that will always be in high demand.</p>

<h2 id="stocks-are-also-a-form-of-ownership">Stocks Are Also a Form of Ownership</h2>

<p>Even more important is a second consideration.</p>

<p>Ownership isn’t limited to real estate.</p>

<p>A stock is also a form of ownership.</p>

<p>If, in the future, companies own millions of robots, operate AI infrastructure, produce energy, and control automated factories, these means of production ultimately belong to their shareholders.</p>

<p>Stocks could therefore represent an even more direct stake in an automated economy than real estate.</p>

<p>Real estate is primarily a stake in <strong>location and land scarcity</strong>.</p>

<p>Company shares, on the other hand, are a stake in <strong>productivity and capital</strong>.</p>

<p>Anyone who wants to protect themselves against a future in which labor loses importance relative to capital should therefore not necessarily try to predict exactly which individual asset will gain value.</p>

<p>The more robust idea is broader:</p>

<p><strong>Ownership of scarce and productive assets could become more important than relying exclusively on one’s own earned income.</strong></p>

<h2 id="musks-prediction-is-by-no-means-the-scientific-consensus">Musk’s prediction is by no means the scientific consensus</h2>

<p>The actual extent of AI’s economic impact remains entirely uncertain at this time.</p>

<p>Daron Acemoglu, for example, arrives at a significantly more conservative estimate than Musk. In <em>The Simple Macroeconomics of AI</em>, he estimates that the additional increase in total factor productivity (TFP) resulting from the AI wave foreseeable at that time would amount to no more than about 0.66 percent over ten years (<a href="https://www.nber.org/papers/w32487">Acemoglu, NBER Working Paper 32487</a>).</p>

<p>That would be significant, but a far cry from an economy of unlimited abundance.</p>

<p>On the other hand, there is the exceptionally rapid progress of modern AI systems and research such as that by METR, which shows that the length of tasks that can be solved autonomously is currently increasing at an astonishingly rapid pace.</p>

<p>Both can be true at the same time.</p>

<p>Today’s economic impact may still be relatively small, while technical capabilities are growing very rapidly.</p>

<p>That is precisely why long-term forecasts are so difficult at the moment.</p>

<p>The gap between Acemoglu’s more evolutionary change and Musk’s post-economic world is not a matter of a few percentage points, but rather two fundamentally different visions of the future.</p>

<h2 id="what-might-the-year-2036-actually-look-like">What might the year 2036 actually look like?</h2>

<p>A completely cashless society by 2036 seems extremely unlikely.</p>

<p>A plausible—but by no means certain—scenario, however, would be a significantly transformed world of work.</p>

<p>By then, AI could be as commonplace for many forms of intellectual work as the internet is today. A single person could perform tasks that, in the early 2020s, still required entire teams.</p>

<p>Many simple digital tasks could be largely automated. Some professions might have disappeared, while others would undergo fundamental changes. Entering many traditional knowledge-based professions is likely to become more difficult.</p>

<p>At the same time, robotics could have taken over large parts of industry, logistics, and agriculture. General-purpose robots could also be widespread in everyday life for the first time, without yet being able to replace every human activity.</p>

<p>As a result, many services and industrial products could become significantly cheaper.</p>

<p>But land in attractive locations would remain scarce. Natural resources would remain limited. Energy, infrastructure, and computing power would still need to be produced. People would continue to compete for certain goods.</p>

<p>Money would therefore probably not disappear.</p>

<p>But something else could happen:</p>

<p><strong>The link between work and prosperity could weaken.</strong></p>

<h2 id="and-what-if-at-some-point-almost-no-one-really-has-to-work-anymore">And what if, at some point, almost no one really has to work anymore?</h2>

<p>At that point, at the latest, the technical question would become a political one.</p>

<p>A society would come under considerable political and social pressure if nearly all production were automated, yet the means of production were owned by only a small portion of the population, while the rest would be unable to earn much, if any, income from work.</p>

<p>The pressure for forms of redistribution or for broader participation in productive capital would then likely increase significantly.</p>

<p>This could take the form of an unconditional basic income. It could involve citizen funds whose members collectively own shares in the automated economy. Governments could tax capital more heavily or hold stakes themselves. Another possibility would be a kind of social dividend based on the productivity of AI and robotics.</p>

<p>Musk occasionally refers to such a future as “Universal High Income” (<a href="https://www.forbes.com/sites/siladityaray/2026/04/17/elon-musk-touts-universal-income-as-remedy-to-ai-driven-unemployment/">Forbes, April 2026</a>).</p>

<p>Perhaps money would then actually be less important for basic needs.</p>

<p>But even then, there would likely still be things that not everyone can have at the same time.</p>

<p>And so scarcity would remain.</p>

<h2 id="conclusion">Conclusion</h2>

<p>Elon Musk’s statement that money will no longer play a role as early as 2036 seems exaggerated.</p>

<p>However, the fundamental idea behind it is far more interesting than the specific prediction.</p>

<p>If artificial intelligence takes over intellectual work and robotics increasingly takes over physical labor, the costs of many goods and services could drop dramatically. Labor would then no longer be the central limiting factor in our economy.</p>

<p>But scarcity would not disappear as a result.</p>

<p>Land, prime locations, natural resources, energy, infrastructure, and ultimately ownership of the machines that produce this new prosperity will remain limited.</p>

<p>Perhaps that is why the AI revolution will not lead to ownership becoming unimportant.</p>

<p><strong>Perhaps the exact opposite will happen.</strong></p>

<p>For many people today, their labor is their most important economic asset. If the relative value of that labor declines while automated means of production continue to generate returns for their owners, ownership could play a greater role in the distribution of wealth than it does today.</p>

<p>However, this does not mean that one should rush out and buy any real estate as quickly as possible.</p>

<p>The far more robust conclusion is:</p>

<p><strong>If we are indeed heading toward a highly automated economy, it might make more sense to convert a portion of today’s earned income into assets that are permanently scarce or productive—such as real estate and broadly diversified corporate equity.</strong></p>

<p>The truly crucial question for the coming decades may therefore not be whether AI will take our jobs away.</p>

<p>Rather:</p>

<p><strong>Who owns the world when machines do the work?</strong></p>]]></content><author><name>Matthias Munz</name></author><category term="ChatWithGPT" /><summary type="html"><![CDATA[In an interview with The Economist in July 2026, Elon Musk made a remarkable prediction: “Money won’t matter in 2036.” In other words, money will no longer play a significant role in just ten years (The Economist, Interview with Elon Musk).]]></summary></entry><entry xml:lang="en"><title type="html">Why right-wing populism and authoritarian politics are gaining ground again</title><link href="https://matthiasmunz.de/en/ChatWithGPT_Autoritaere_Ideen/" rel="alternate" type="text/html" title="Why right-wing populism and authoritarian politics are gaining ground again" /><published>2026-08-09T00:00:00+02:00</published><updated>2026-08-06T22:05:22+02:00</updated><id>https://matthiasmunz.de/ChatWithGPT_Autoritaere_Ideen</id><content type="html" xml:base="https://matthiasmunz.de/ChatWithGPT_Autoritaere_Ideen/"><![CDATA[<p>Liberal democracies were long regarded as the successful alternative to fascism, Nazism, and communist dictatorships. By the end of the Cold War, at the latest, the direction seemed clear: more democracy, more freedom, and more international cooperation.</p>

<p>But this self-image has become fragile. Right-wing populist parties are gaining support, democratic institutions are under open attack, and the promise of strong leadership no longer appears to some people as a threat, but rather as a solution.</p>

<p>Authoritarian politics is not regaining appeal because large segments of the population suddenly reject democracy on principle. It gains support where democratic institutions are perceived as slow, powerless, or far removed from everyday life. Economic uncertainty, loss of status and control, cultural conflicts, mistrust, and political polarization reinforce one another. Authoritarian movements offer simple answers to these issues, clear culprits, and the promise of order and the ability to take action.</p>

<p>A recent snapshot from Germany illustrates just how evident this shift has become. In the federal election on February 23, 2025, the CDU/CSU received 28.5 percent of the second votes, while the AfD received 20.8 percent (<a href="https://bundeswahlleiterin.de/bundestagswahlen/2025/ergebnisse.html">Federal Returning Officer, 2025</a>). In the ARD DeutschlandTrend survey of August 6, 2026, the results of the “Sunday poll” were reversed: The Union reached 21 percent, while the AfD reached 28 percent—its highest result to date in this survey (<a href="https://www.tagesschau.de/inland/deutschlandtrend/deutschlandtrend-august-100.html">ARD-DeutschlandTrend, 2026</a>).</p>

<p>International comparative data also point to a decline in democracy. According to the V-Dem Democracy Report 2026, nearly a quarter of the world’s countries were undergoing a process of autocratization in 2025. Freedom House reported that 2025 marked the twentieth consecutive year of a global decline in political rights and civil liberties (<a href="https://v-dem.net/news/press-release-democratic-backsliding-reaches-western-democracies-with-us-decline-unprecedented/">Nord et al., V-Dem Democracy Report, 2026</a>; <a href="https://freedomhouse.org/report/freedom-world/2026/growing-shadow-autocracy">Gorokhovskaia et al., Freedom in the World, 2026</a>).</p>

<p>How did this happen?</p>

<h2 id="disclaimer">Disclaimer</h2>
<p>In my blog series “Chat with GPT”, I ask <a href="https://www.chatgpt.com">ChatGPT</a> on a variety of topics, from world politics to everyday issues, to get concise summaries and answers. The answers provided by ChatGPT are generated from large datasets, which may include biases, for example from Western perspectives. While the model strives for accuracy, it can sometimes produce incorrect or misleading information. I do not take responsibility for the validity of the content. Though I aim to ensure that the answers reflect common sense, I encourage you to cross-check facts and verify information through trusted sources. You are also welcome to reach out to me with suggestions for improvement.</p>

<h2 id="why-simple-answers-are-appealing">Why simple answers are appealing</h2>
<p>Democracy thrives on balancing differing interests. Decisions take time, compromises are necessary, and the results rarely satisfy everyone involved.</p>

<p>Especially in times of crisis, this system can seem slow, contradictory, and ineffective. Authoritarian politicians, on the other hand, promise clarity. They present simple solutions to complex problems, point the finger at those to blame, and give the impression that they can act decisively.</p>

<p>This can become appealing when people feel that, while democratic institutions engage in lengthy debate, they fail to solve key problems. The desire for strong leadership does not necessarily stem from a fundamental rejection of democracy. Often, it begins with the hope for more order and the ability to take action.</p>

<p>The danger lies in the fact that democratic checks and balances can quickly come to be seen as disruptive obstacles: courts delay decisions, parliaments debate for too long, the media ask uncomfortable questions, and the opposition blocks political initiatives. What is actually intended to limit power is portrayed as a sign of weakness (<a href="https://www.penguinrandomhouse.com/books/562246/how-democracies-die-by-steven-levitsky-and-daniel-ziblatt/">Levitsky &amp; Ziblatt, 2018</a>).</p>

<h2 id="loss-of-control-uncertainty-and-loss-of-status">Loss of control, uncertainty, and loss of status</h2>
<p>Many people view the past decades as a period of profound change. Globalization, digitalization, migration, climate change, artificial intelligence, and geopolitical crises are transforming the economy and society at a rapid pace.</p>

<p>Objectively speaking, one’s own life may not even have gotten worse. Politically, the mere feeling of losing control over the future is often enough to make a difference.</p>

<p>Those who believe they are falling behind economically, no longer understand social changes, or see the familiar order under threat become more receptive to political proposals that promise security, isolation, and national self-determination.</p>

<p>This is not just about absolute poverty. The fear of social decline and comparisons with others also play an important role. People may perceive their situation as unfair if they believe they receive less recognition than other groups or are losing status compared to previous generations.</p>

<p>Studies suggest that economic and cultural explanations cannot be clearly distinguished from one another. Economic change can be experienced as a material loss, but also as a loss of recognition, social status, and cultural security (<a href="https://doi.org/10.1111/1468-4446.12319">Gidron &amp; Hall, British Journal of Sociology, 2017</a>).</p>

<p>Right-wing populist movements capitalize on such experiences. They often link economic concerns to cultural or national conflicts and blame elites, international institutions, or social minorities.</p>

<p>However, economic insecurity does not automatically lead to authoritarian attitudes. It also depends on how political parties explain changes, which conflicts they highlight, and what solutions they offer.</p>

<h2 id="trust-representation-and-established-parties">Trust, representation, and established parties</h2>
<p>Democratic systems depend on citizens trusting their institutions, at least in principle. This level of trust varies significantly across countries, institutions, and demographic groups. It is often particularly low among people who believe they have no influence over political decisions.</p>

<p>The 2024 OECD Trust Survey reveals a clear correlation between the sense of political participation and trust in the national government. Among respondents who felt they had influence over government actions, 69 percent trusted the national government. Among those who did not perceive such influence, the figure was only 22 percent (<a href="https://www.oecd.org/en/publications/oecd-survey-on-drivers-of-trust-in-public-institutions-2024-results_9a20554b-en.html">OECD, 2024</a>).</p>

<p>To many people, however, politics seems far removed from their everyday lives. Government agencies are perceived as slow, political decisions as difficult to understand, and political parties as indistinguishable from one another. Scandals, broken promises, and contradictory crisis communications can reinforce this impression.</p>

<p>At the same time, traditional mainstream parties in many countries have lost some of their former appeal. They barely reach certain social groups anymore, and in their language, personnel, and priorities, they sometimes seem far removed from those groups’ everyday lives.</p>

<p>When people feel that their own vote won’t make a difference anyway, politicians who present themselves as opponents of the entire system become attractive. They don’t have to convincingly prove that they can solve problems better. Often, it is enough for them to credibly embody anger, disappointment, and rejection.</p>

<p>Their limited political experience can even become an advantage in a climate of mistrust. Those who have not previously held positions of responsibility can more easily claim that they are not part of the problem.</p>

<h2 id="identity-cultural-change-and-nationalism">Identity, cultural change, and nationalism</h2>
<p>Political conflicts are no longer just about wages, taxes, or social benefits. They are increasingly centered on migration, religion, gender roles, language, social recognition, and cultural values.</p>

<p>For some people, these changes mean greater freedom and equality. Others experience them as a loss of orientation, status, or cultural security.</p>

<p>An influential explanation for the success of authoritarian populism is therefore the theory of “cultural backlash.” It describes a backlash against social liberalization and the transformation of traditional norms. However, the significance of this mechanism is controversial in research and should not be understood as the sole explanation (<a href="https://doi.org/10.1017/9781108595841">Norris &amp; Inglehart, 2019</a>; <a href="https://doi.org/10.1146/annurev-polisci-041719-102503">Berman, Annual Review of Political Science, 2021</a>).</p>

<p>In this situation, nationalist movements offer a seemingly simple model of social order. They promise a sense of belonging, a shared identity, and a clear boundary between “us” and “them.”</p>

<p>Nationalism is not automatically undemocratic. A nation can also be understood as a political community bound by shared democratic rules and equal civil rights. Nationalism becomes problematic when belonging is defined primarily by origin, religion, ethnic descent, or cultural conformity. In such cases, certain segments of the population are no longer regarded as equal members of the political community (<a href="https://doi.org/10.1146/annurev-polisci-041719-101841">Mylonas &amp; Tudor, Annual Review of Political Science, 2021</a>).</p>

<h2 id="social-media-an-amplifier-but-not-the-sole-cause">Social media: an amplifier, but not the sole cause</h2>
<p>Social media has fundamentally transformed political communication.</p>

<p>Content competes for attention on these platforms. Outrage, fear, and moral indignation often generate a particularly high number of reactions. Likes, comments, and shares can contribute to users repeating similar messages and platforms showing them comparable content more frequently.</p>

<p>Studies on Twitter showed that positive social feedback on outraged posts increased the likelihood of further expressions of outrage. Users also adapted their language to the norms of their respective social networks (<a href="https://doi.org/10.1126/sciadv.abe5641">Brady et al., Science Advances, 2021</a>).</p>

<p>Simplified and emotionally charged messages thus often spread more easily than nuanced explanations. Political opponents quickly come to be seen not as people with different interests, but as enemies, traitors, or threats.</p>

<p>Research, however, challenges the simplistic claim that social media or its algorithms are solely responsible for political polarization. In a large-scale Facebook experiment, the visibility of politically aligned sources was reduced by about one-third. This did not result in any measurable change in the participants’ political attitudes or affective polarization (<a href="https://doi.org/10.1038/s41586-023-06297-w">Nyhan et al., Nature, 2023</a>).</p>

<p>In contrast, a recent field study on X concluded that the targeted upvoting or downvoting of posts containing anti-democratic statements and partisan hostility can influence attitudes toward the opposing political camp. The measured effects were present but limited and related to a specific intervention in a specific usage context (<a href="https://doi.org/10.1126/science.adu5584">Piccardi et al., Science, 2025</a>).</p>

<p>The results are not necessarily contradictory. Rather, they show that it depends on what content is altered, how an algorithm intervenes, which platform is being studied, and how long an intervention lasts.</p>

<p>Social media should therefore be understood primarily as amplifiers and distribution infrastructures. They can make existing conflicts more visible, accelerate their spread, and facilitate the normalization of conspiracy narratives or misanthropic statements. However, they are not the sole cause of social polarization.</p>

<h2 id="polarization-changes-the-standards">Polarization changes the standards</h2>
<p>In highly polarized societies, the focus is increasingly shifting away from which policies make objective sense. What becomes decisive is which side wins.</p>

<p>Political opponents are no longer viewed as legitimate rivals, but as an existential threat. This can lead to a growing willingness to undermine democratic rules, as long as it benefits one’s own side.</p>

<p>An experiment in the U.S. showed that voters often punished violations of democratic principles only to a limited extent if the candidate in question aligned with their own political orientation. The greater the political distance from the opposing side, the less willing voters were to vote for a candidate from the other camp due to a violation of democratic principles (<a href="https://doi.org/10.1017/S0003055420000052">Graham &amp; Svolik, American Political Science Review, 2020</a>).</p>

<p>People may then accept attacks on the courts, the media, or electoral procedures because they believe this is the only way to stop an even more dangerous opponent.</p>

<p>Authoritarian politics, therefore, does not always arise from an openly expressed rejection of democracy. It can also grow out of the conviction that democratic rules must be temporarily set aside in the face of a supposed exceptional situation.</p>

<h2 id="distinguishing-between-populism-nationalism-authoritarianism-and-fascism">Distinguishing between populism, nationalism, authoritarianism, and fascism</h2>
<p>These terms are often conflated in public debates, but they describe different phenomena.</p>

<p><em>Populism</em> pits a supposedly unified and morally good people against corrupt or self-serving elites. Its frequently anti-pluralist core is particularly problematic: Populists not only claim to represent the people, but sometimes assert that they alone embody the true will of the people (<a href="https://doi.org/10.1093/actrade/9780190234874.001.0001">Mudde &amp; Rovira Kaltwasser, 2017</a>).</p>

<p><em>Nationalism</em> declares the nation to be the most important political point of reference. It can be democratic and civic in orientation, but it can also take on an ethnic, exclusionary, or aggressive character.</p>

<p><em>Authoritarianism</em> favors concentrated political power and strong leadership. Democratic checks and balances, political competition, and individual freedoms are thereby restricted or viewed as obstacles.</p>

<p><em>Fascism</em> continues. It combines radical nationalism with an authoritarian leadership model, a rejection of pluralistic democracy, and the idea of a national rebirth. Historically, it has also included mass political mobilization, the glorification of violence, and the systematic exclusion of certain groups (<a href="https://www.penguinrandomhouse.com/books/128540/the-anatomy-of-fascism-by-robert-o-paxton/">Paxton, 2004</a>).</p>

<p>Not every populist is a fascist, and not every nationalist rejects democracy. Nor are conservative or anti-immigration positions automatically authoritarian.</p>

<p>Nevertheless, the lines between them can be blurred. Populist rhetoric can delegitimize democratic institutions. Exclusionary nationalism can justify unequal civil rights. Authoritarian governments can gradually restrict the space for opposition, the media, and civil society.</p>

<p>This is precisely why it is important to use these terms precisely. Those who label every right-wing position as fascist blur the distinctions and make it harder to identify genuinely fascist characteristics.</p>

<h2 id="democracies-often-erode-gradually">Democracies often erode gradually</h2>
<p>In established democracies today, the transition to an authoritarian system often does not occur through a sudden coup d’état.</p>

<p>Governments are initially legitimized through largely free elections. Afterward, they gradually change the political rules of the game. Independent courts are weakened, critical media are pressured, state institutions are filled with partisan appointees, and the rights of minorities are curtailed.</p>

<p>Elections may still take place. However, they become increasingly unfair because the government and the opposition no longer compete under the same conditions.</p>

<p>Political scientist Nancy Bermeo describes this process as “executive aggrandizement”: elected governments gradually expand their power and weaken the institutions meant to keep them in check (<a href="https://doi.org/10.1353/jod.2016.0012">Bermeo, Journal of Democracy, 2016</a>).</p>

<p>It is precisely this creeping process that makes democratic regression difficult to detect. Each individual measure may seem limited or technically justified. Only when taken together do these interventions fundamentally alter the political system.</p>

<p>This does not mean that coups d’état and overt violence have disappeared. Military coups, armed conflicts, attacks on democratic institutions, and direct repression remain major causes of the loss of political freedom worldwide (<a href="https://freedomhouse.org/report/freedom-world/2026/growing-shadow-autocracy">Gorokhovskaia et al., Freedom in the World, 2026</a>).</p>

<h2 id="what-democracies-can-do-about-it">What democracies can do about it</h2>
<p>Moral outrage alone will not stop authoritarian movements. A blanket dismissal of their voters is no substitute for a political response and can further deepen existing alienation. However, this does not mean that anti-democratic statements or attacks on minorities should be downplayed.</p>

<p>Democracies must demonstrate that they are capable of taking action. This includes functioning administrations, reliable public infrastructure, social security, and political decisions whose goals and consequences are explained in a transparent manner.</p>

<p>People also need real opportunities to exert influence and be heard. Participatory processes must not be merely symbolic. Political feedback must be visibly incorporated into decisions. The strong correlation between perceived participation and institutional trust demonstrates how important political effectiveness is for the stability of a democracy ([OECD, 2024] (https://www.oecd.org/en/publications/oecd-survey-on-drivers-of-trust-in-public-institutions-2024-results_9a20554b-en.html)).</p>

<p>Equally important are independent courts, a free press, transparent government agencies, political education, and an active civil society.</p>

<p>Democratic principles must be defended even when one’s own political camp might benefit in the short term from their weakening. This includes the willingness to accept electoral defeats, to recognize the opposition as legitimate, and to allow for a peaceful transfer of power.</p>

<p>Democracy thrives not only on elections. It thrives on the limitation of political power and the protection of those who do not belong to the prevailing majority.</p>

<h2 id="conclusion">Conclusion</h2>
<p>Authoritarian and nationalist ideas do not suddenly become appealing again simply because Western societies have completely forgotten their history.</p>

<p>Their appeal grows when several developments converge: economic uncertainty, loss of status and control, social change, lack of trust, cultural conflicts, digital amplification, and political polarization.</p>

<p>Authoritarian movements offer simple answers to real fears. They promise order, a sense of belonging, and the ability to take action. These promises become particularly appealing where democratic politics seem complicated and problems remain visibly unresolved.</p>

<p>This development is not inevitable. Democracies can regain trust if they effectively solve problems, enable social participation, and credibly defend their own rules.</p>

<p>Democracy is slow, contradictory, and sometimes frustrating. It is precisely this that forces different interests to find common ground and limits political power. This is not its weakness, but its decisive strength.</p>]]></content><author><name>Matthias Munz</name></author><category term="ChatWithGPT" /><summary type="html"><![CDATA[Why are right-wing populism, nationalism, and authoritarian ideas gaining support again? The main causes - from a loss of control to polarization.]]></summary></entry><entry xml:lang="en"><title type="html">The Pfaffenwinkel Milk Trail: A short loop trail with a cheese farm</title><link href="https://matthiasmunz.de/en/Milchweg/" rel="alternate" type="text/html" title="The Pfaffenwinkel Milk Trail: A short loop trail with a cheese farm" /><published>2026-07-26T00:00:00+02:00</published><updated>2026-06-30T15:54:38+02:00</updated><id>https://matthiasmunz.de/Milchweg</id><content type="html" xml:base="https://matthiasmunz.de/Milchweg/"><![CDATA[<p>The <a href="https://www.pfaffenwinkler-milchweg.de/">Pfaffenwinkel Milk Trail</a> near Rottenbuch is a lovely little loop trail through meadows and pastures. Over the course of about <a href="#komoot">4 kilometers</a>, the trail takes you past cows, beautiful views, and several informational stations about milk, agriculture, and cheese.</p>

<figure class="third ">
  
    
      <a href="/assets/images/2026-07-26-Milchweg/Milchweg_1.jpg" title="The Milky Way Rules.">
          <img src="/assets/images/2026-07-26-Milchweg/Milchweg_1_th.jpg" alt="The Milky Way Rules." />
      </a>


      <a href="/assets/images/2026-07-26-Milchweg/Milchweg_2.jpg" title="The electrical distribution box that looks like a piece of cheese.">
          <img src="/assets/images/2026-07-26-Milchweg/Milchweg_2_th.jpg" alt="The electrical distribution box that looks like a piece of cheese." />
      </a>


      <a href="/assets/images/2026-07-26-Milchweg/Milchweg_3.jpg" title="Caution: People with canes and long hair may be in this area or crossing the street.">
          <img src="/assets/images/2026-07-26-Milchweg/Milchweg_3_th.jpg" alt="Caution: People with canes and long hair may be in this area or crossing the street." />
      </a>


      <a href="/assets/images/2026-07-26-Milchweg/Milchweg_4.jpg" title="A magnificent view across meadows and pastures.">
          <img src="/assets/images/2026-07-26-Milchweg/Milchweg_4_th.jpg" alt="A magnificent view across meadows and pastures." />
      </a>


      <a href="/assets/images/2026-07-26-Milchweg/Milchweg_5.jpg" title="A stop at the Schönegger Käse-Alm along the way.">
          <img src="/assets/images/2026-07-26-Milchweg/Milchweg_5_th.jpg" alt="A stop at the Schönegger Käse-Alm along the way." />
      </a>


</figure>

<p>The trail isn’t long, but it’s pleasantly varied and easy to manage, especially with children. The signs along the route make the walk entertaining without it feeling like a typical nature trail. We especially loved the open views across the pastures and the small, charming details along the way.</p>

<p>A definite highlight is the <a href="https://www.schoenegger.com/">Schönegger Käse-Alm</a>, located right along the trail. It’s a great place to stop and round out your outing with some cheese, a snack, or something sweet.</p>

<h2 id="komoot">Komoot</h2>
<iframe src="https://www.komoot.com/tour/3072092474/embed?share_token=a4z6B7Kw7xSIm48Sz9qQv7AhqDbEx0bWWUt5CYxeqwBqF9VLO9&amp;hl=de&amp;layout=classic&amp;profile=1" width="100%" height="700" frameborder="0" scrolling="no"></iframe>]]></content><author><name>Matthias Munz</name></author><category term="Excursions" /><summary type="html"><![CDATA[The Pfaffenwinkel Milk Trail near Rottenbuch is a lovely little loop trail through meadows and pastures. Over the course of about 4 kilometers, the trail takes you past cows, beautiful views, and several informational stations about milk, agriculture, and cheese.]]></summary></entry><entry xml:lang="en"><title type="html">The Loisach River near Schönmühl — a great spot for swimming on hot days in Penzberg</title><link href="https://matthiasmunz.de/en/Schoenmuehl_Loisach/" rel="alternate" type="text/html" title="The Loisach River near Schönmühl — a great spot for swimming on hot days in Penzberg" /><published>2026-07-19T00:00:00+02:00</published><updated>2026-06-30T15:54:38+02:00</updated><id>https://matthiasmunz.de/Schoenmuehl_Loisach</id><content type="html" xml:base="https://matthiasmunz.de/Schoenmuehl_Loisach/"><![CDATA[<p>The Loisach River near <a href="https://de.wikipedia.org/wiki/Sch%C3%B6nm%C3%BChl">Schönmühl</a> is our favorite spot for swimming on particularly hot days. When the water everywhere else has already heated up, the river here usually stays pleasantly cool and clear. From downtown Penzberg, you can reach the spot by bike in about 10–15 minutes. Along a <a href="#komoot">dirt path</a>, there are several spots where you can spread out your towel right by the water and enjoy the cool water.</p>

<figure class="third ">
  
    
      <a href="/assets/images/2026-07-19-Schoenmuehl_Loisach/Schoenmuehl_Loisach_1.jpg" title="The Loisach River near Schönmühl.">
          <img src="/assets/images/2026-07-19-Schoenmuehl_Loisach/Schoenmuehl_Loisach_1_th.jpg" alt="The Loisach River near Schönmühl." />
      </a>


      <a href="/assets/images/2026-07-19-Schoenmuehl_Loisach/Schoenmuehl_Loisach_2.jpg" title="We often come by bike.">
          <img src="/assets/images/2026-07-19-Schoenmuehl_Loisach/Schoenmuehl_Loisach_2_th.jpg" alt="We often come by bike." />
      </a>


      <a href="/assets/images/2026-07-19-Schoenmuehl_Loisach/Schoenmuehl_Loisach_3.jpg" title="A dragonfly in the foreground.">
          <img src="/assets/images/2026-07-19-Schoenmuehl_Loisach/Schoenmuehl_Loisach_3_th.jpg" alt="A dragonfly in the foreground." />
      </a>


</figure>

<p>We often enter the water just before the railroad bridge and let ourselves drift downstream for about 100–150 meters to the signposted canoe exit. The water there is usually relatively shallow, and the current is pleasant. The <a href="/en/Loisach_SUP/">SUP tour starting in Kochel</a> also ends at the canoe exit.</p>

<h2 id="komoot">Komoot</h2>
<iframe src="https://www.komoot.com/tour/3072097695/embed?share_token=awTz4seBKE8VtHZoqJkOJLfvU2kSvs6rxib9dq7BgG862F7Spr&amp;hl=de&amp;layout=map" width="100%" height="540" frameborder="0" scrolling="no"></iframe>]]></content><author><name>Matthias Munz</name></author><category term="Excursions" /><summary type="html"><![CDATA[The Loisach River near Schönmühl is our favorite spot for swimming on particularly hot days. When the water everywhere else has already heated up, the river here usually stays pleasantly cool and clear. From downtown Penzberg, you can reach the spot by bike in about 10–15 minutes. Along a dirt path, there are several spots where you can spread out your towel right by the water and enjoy the cool water.]]></summary></entry><entry xml:lang="en"><title type="html">MapifyGPX.de: Easily convert GPX waypoints to map links</title><link href="https://matthiasmunz.de/en/MapifyGPX/" rel="alternate" type="text/html" title="MapifyGPX.de: Easily convert GPX waypoints to map links" /><published>2026-07-05T00:00:00+02:00</published><updated>2026-07-05T12:59:27+02:00</updated><id>https://matthiasmunz.de/MapifyGPX</id><content type="html" xml:base="https://matthiasmunz.de/MapifyGPX/"><![CDATA[<p>What started as a small solution for the family is now being actively used: the platform <strong><a href="https://mapifygpx.de/en/">mapifygpx.de</a></strong> is a side project of mine and has been online for several months. There, I provide small free apps that process GPX files (GPS Exchange Format) and solve everyday problems around routes, waypoints, and navigation.</p>

<p>The first available app, <strong><a href="https://mapifygpx.de/en/app-waypoint2maps/">Waypoint2Maps</a></strong>, converts waypoints from GPX files into direct links for Google Maps and Apple Maps. Instead of manually copying coordinates or switching back and forth between different apps, users get a clear list of clickable links.</p>

<p>The idea originally came from my father. He had repeatedly asked me to generate such links for him so that he could use waypoints more easily for navigation on his motorhome trips. This recurring small task eventually led to the creation of <a href="https://mapifygpx.de/en/">mapifygpx.de</a>.</p>

<p>Technically, <a href="https://mapifygpx.de/en/">mapifygpx.de</a> is based on a deliberately lean setup: I develop the actual apps in <strong>R/Shiny</strong> and host them via <strong><a href="https://www.shinyapps.io/">shinyapps.io</a></strong>. The accompanying website is built with <strong>Jekyll</strong> and the <strong>Minimal Mistakes</strong> theme and is provided via <strong>GitHub</strong>. What is particularly interesting to me is that I continuously develop the apps further based on user feedback and add practical details.</p>]]></content><author><name>Matthias Munz</name></author><category term="Programming" /><summary type="html"><![CDATA[What started as a small solution for the family is now being actively used: the platform mapifygpx.de is a side project of mine and has been online for several months. There, I provide small free apps that process GPX files (GPS Exchange Format) and solve everyday problems around routes, waypoints, and navigation.]]></summary></entry><entry xml:lang="en"><title type="html">Our First Year with Our Campervan: Summary and Statistics</title><link href="https://matthiasmunz.de/en/Campervan_Fazit/" rel="alternate" type="text/html" title="Our First Year with Our Campervan: Summary and Statistics" /><published>2026-06-28T00:00:00+02:00</published><updated>2026-08-18T21:39:22+02:00</updated><id>https://matthiasmunz.de/Campervan_Fazit</id><content type="html" xml:base="https://matthiasmunz.de/Campervan_Fazit/"><![CDATA[<p>In the spring of 2025, our family bought a campervan. We’ve been on the road with it a few times since then—and what can I say: we’re pretty thrilled. By now, we’ve also taken care of the repairs and warranty claims that came up after the purchase. So it’s time for a little update from our little vacation home on wheels.</p>

<h2 id="our-campervan">Our Campervan</h2>
<p>Our campervan is a <a href="https://www.dethleffs.com/dethleffs/04_INT/02_pdfs/03_camper-vans/int_kat_24_camper_van.pdf">Dethleffs Globetrail Classic 600 DK</a> based on the Fiat Ducato 9, featuring a pop-up roof, chassis and electrical packages, an awning, an ESX navigation radio, and a backup camera. It originally came from the former rental fleet of the now-bankrupt Mönchengladbach-based RV rental company <a href="https://rp-online.de/nrw/staedte/moenchengladbach/wohnmobile-in-moenchengladbach-das-ende-von-roadfans-mitarbeiter-standorte-werkstaetten_aid-125139865">Roadfans</a>. At the time of purchase, it was just under a year old and had about 13,000 kilometers on the odometer.</p>

<p><a href="/assets/images/2026-06-28-Campervan_Fazit/Campervan_Grundriss.jpg" class="image-popup" title="Floor plan of the Dethleffs Globetrail Classic 600 DK camper van." alt="Floor plan of the Dethleffs Globetrail Classic 600 DK camper van.">
  <img class="align-center" src="/assets/images/2026-06-28-Campervan_Fazit/Campervan_Grundriss_th.jpg" title="Floor plan of the Dethleffs Globetrail Classic 600 DK camper van." alt="Floor plan of the Dethleffs Globetrail Classic 600 DK camper van." />
</a></p>

<h2 id="purchase-price--upgrades">Purchase Price &amp; Upgrades</h2>
<p>The purchase price was €51,211. According to the <a href="https://tirge.de/ wp-content/uploads/2024/06/Preisliste_Camper_Vans___Urban_Camper_03-2024_DE_deutsch.pdf">Dethleffs Price List for Camper Vans &amp; Urban Campers 2024</a>, the list price for the 2024 model year in this configuration is €70,742, which is made up of the following items:</p>

<ul>
  <li>Base price: €56,999</li>
  <li>Pop-up roof: €5,999</li>
  <li>Insulated and heated wastewater tank: €1,299</li>
  <li>Chassis package: €2,199 (special price)</li>
  <li>Electrical package: €249 (special price)</li>
  <li>Backup camera: €399</li>
  <li>Navigation radio: €2,299</li>
  <li>Awning: €1,299</li>
</ul>

<p>With upgrades such as the <a href="https://www.thule.com/de-de/news/thule-veloswing">Thule VeloSwing trailer hitch</a>, <a href="https://system-regal.com/Kastenwagen">SYSRACK heavy-duty slide-out</a>, a <a href="https://www.alugas.de/de/produkt-caravan-1">refillable propane tank</a>, a <a href="https://amzn.to/43NPh29">320-Ah LiFePO4 auxiliary battery</a>, a <a href="https://www.truma.com/de/produkte/gasversorgung/gasdruckregler/duocontrol-cs/">Truma DuoControl CS Gas Pressure Regulator</a>, better speakers, sound insulation on the driver’s and passenger’s doors, anti-theft protection on the driver’s and rear doors, and all sorts of accessories, the total cost has risen to about €58,500. I installed all the upgrades myself.</p>

<h2 id="defects">Defects</h2>
<p>After the purchase, in addition to minor defects (e.g., missing cover caps, a missing rubber seal around the access point to the pop-up roof, screw covers coming loose, a screw on the door that wasn’t fully tightened at the factory, and a defective microswitch on the faucet), more significant problems also became apparent. These included water leakage at the access point to the pop-up roof because the adhesive seal on the spoiler in front of the pop-up roof wasn’t fully watertight, as well as sometimes severe interference noise with the navigation radio. At first glance, that sounds like quite a lot, and yes, it did take quite a bit of time for emails, phone calls, coordination with the repair shop, and, in some cases, troubleshooting. However, given all the reviews I’d read and watched before buying, this didn’t come as a complete surprise to me. Fortunately, it didn’t stop us from taking our planned trips. By now, all known defects have been fixed and were covered by the dealer’s warranty or the manufacturer’s guarantee. One payment is still pending, but overall, I’m glad that this chapter is now largely closed.</p>

<h2 id="overnight-stays-in-2025">Overnight Stays in 2025</h2>
<p>In 2025, we’ve already taken several vacations in our new campervan. By now, we’ve found a good rhythm when it comes to packing, driving, arriving, and going about our daily lives in our mobile home. We’ve really enjoyed the vacations so far. In total, we spent 49 nights in the campervan, spread across the following trips:</p>

<ul>
  <li><a href="/en/Marina_di_Venezia/">Easter break – Marina di Venezia</a>: 7 nights</li>
  <li>Legoland in May: 2 nights</li>
  <li>Pentecost break – Southern France/Bötzingen: 15 nights</li>
  <li><a href="/en/Sweden-Eastcoast/">Lübeck/Schweden</a>: 21 nights</li>
  <li><a href="/en/Cinque_Terre/">Cinque Terre</a>: 4 nights</li>
</ul>

<h2 id="rental-plans">Rental Plans</h2>
<p>We also plan to launch our own website dedicated to our campervan soon. The plan is to rent it out during the times when we aren’t using it ourselves. This way, it will be put to better use instead of just sitting around most of the time. The domains <strong><a href="http://roadresort.de">roadresort.de</a></strong> and <strong><a href="http://familyfinca.de">familyfinca.de</a></strong> have already been registered.</p>]]></content><author><name>Matthias Munz</name></author><category term="Campervan" /><summary type="html"><![CDATA[In the spring of 2025, our family bought a campervan. We’ve been on the road with it a few times since then—and what can I say: we’re pretty thrilled. By now, we’ve also taken care of the repairs and warranty claims that came up after the purchase. So it’s time for a little update from our little vacation home on wheels.]]></summary></entry><entry xml:lang="en"><title type="html">Structured Data: Turning isolated files into reusable knowledge</title><link href="https://matthiasmunz.de/en/StructuredData/" rel="alternate" type="text/html" title="Structured Data: Turning isolated files into reusable knowledge" /><published>2026-06-18T00:00:00+02:00</published><updated>2026-06-18T15:19:34+02:00</updated><id>https://matthiasmunz.de/StructuredData</id><content type="html" xml:base="https://matthiasmunz.de/StructuredData/"><![CDATA[<p>Structured data often determines whether research stays usable or turns into unusable noise over time. In this post I am (somewhat officially, at least in spirit) declaring July the <em>Structured Data Month</em>, because this topic deserves far more attention than it usually gets in everyday practice.</p>

<h2 id="when-well-structured-files-are-still-unusable">When well-structured files are still unusable</h2>
<p>Imagine a measurement file containing a matrix of numbers. The file itself may be neatly arranged, but it stands alone. The row and column information is somewhere else, the experimental groups are not linked, experimental design and batch information are missing, the processing steps are unclear, and nobody immediately knows where the raw data is stored or whom to contact.</p>

<p>This is an important distinction: <strong>structural formatting is not the same as structural meaning</strong>. A matrix of numbers without metadata, meaning without clear information on what the rows represent, what the columns measure, and what the experimental conditions were, can easily become <strong>dark data</strong>: data that exists, but is difficult or impossible to find, understand, access, or reuse. A file can be neatly formatted and still be scientifically ambiguous. For data to become truly reusable, the relevant information needs to be structured together, and people need to know that this dataset exists. This is what structured data actually means in a modern, data-driven organization.</p>

<h2 id="from-files-to-knowledge-what-structured-data-actually-means">From files to knowledge: what structured data actually means</h2>
<p>Structured data is important because it turns isolated files into reusable knowledge. If data is well described, findable, accessible, and connected to its context, we can ask better questions. We can compare experiments, integrate datasets, detect patterns, reproduce analyses, and generate new hypotheses. This is also the logic behind the <strong><a href="https://www.nature.com/articles/sdata201618">FAIR principles</a></strong>, which argue that scientific data should be <strong>Findable, Accessible, Interoperable, and Reusable</strong>, with a particular emphasis on making data usable not only by people, but also by machines.</p>

<h2 id="the-organizational-reality-everyone-is-cooking-their-own-soup">The organizational reality: everyone is cooking their own soup</h2>
<p>In companies, including pharma and enterprise R&amp;D, this is especially relevant. Data is often generated in different departments, for different projects, with different tools, naming conventions, storage locations, and access rules. In addition, there are often limited incentives to make data reusable for people outside the team that originally generated it. Each team may be “cooking its own soup”. A team may build a spreadsheet that works perfectly for its weekly meeting. Locally, this can be efficient. But if the spreadsheet lacks standardized schemas, shared identifiers, or centralized metadata, it may be completely invisible and useless to a data scientist three doors down who is trying to train a predictive model. This is the classic trap of local optimization and global sub-optimization: something works well for one team, but limits value across the organization.</p>

<p>If nobody knows that a dataset exists, where it is stored, what it contains, or whom to contact, then the data cannot easily contribute to new analyses, new decisions, or new discoveries.</p>

<h2 id="why-this-matters-for-ai-and-machine-learning">Why this matters for AI and machine learning</h2>
<p>This also creates a direct bridge to AI and machine learning. AI systems do not become useful simply because the model is large. They become useful when the data they learn from, retrieve from, or reason over is high quality, well documented, and fit for purpose. In machine learning, data problems can cascade through the whole system, causing errors that are difficult to detect later (<a href="https://research.google/pubs/everyone-wants-to-do-the-model-work-not-the-data-work-data-cascades-in-high-stakes-ai/">Sambasivan 2021</a>). The “data work” may be less glamorous than model building, but it is often the critical step.</p>

<p>For example, if an AI assistant is used for <strong>Retrieval-Augmented Generation (RAG)</strong> to help scientists find past experimental insights, it cannot reason over an isolated spreadsheet. It needs the metadata envelope around the data: sample metadata, definitions of variables, links to protocols, information about data quality, and ideally a documented history of how the data was processed. If we want to train, fine-tune, or retrieve from AI systems, duplicated, inconsistent, biased, mislabeled, or poorly documented data can directly affect performance and reliability. Work on language model training data has shown that deduplication can reduce memorized output and improve model behavior, which is a practical reminder that data preparation is not an administrative detail, but part of model quality itself (<a href="https://aclanthology.org/2022.acl-long.577/">Lee 2022</a>).</p>

<h2 id="conclusion">Conclusion</h2>
<p>Structured data is not an implementation detail but a prerequisite for reuse. Without consistent structure and metadata, data remains tied to its original context and loses value over time. Declaring July as <em>Structured Data Month</em> is a small reminder that improving how we structure and describe data is not optional overhead, but a practical step toward making research and data work more interoperable and sustainable.</p>]]></content><author><name>Matthias Munz</name></author><category term="Programming" /><summary type="html"><![CDATA[Structured data often determines whether research stays usable or turns into unusable noise over time. In this post I am (somewhat officially, at least in spirit) declaring July the Structured Data Month, because this topic deserves far more attention than it usually gets in everyday practice.]]></summary></entry></feed>